
 Connexion

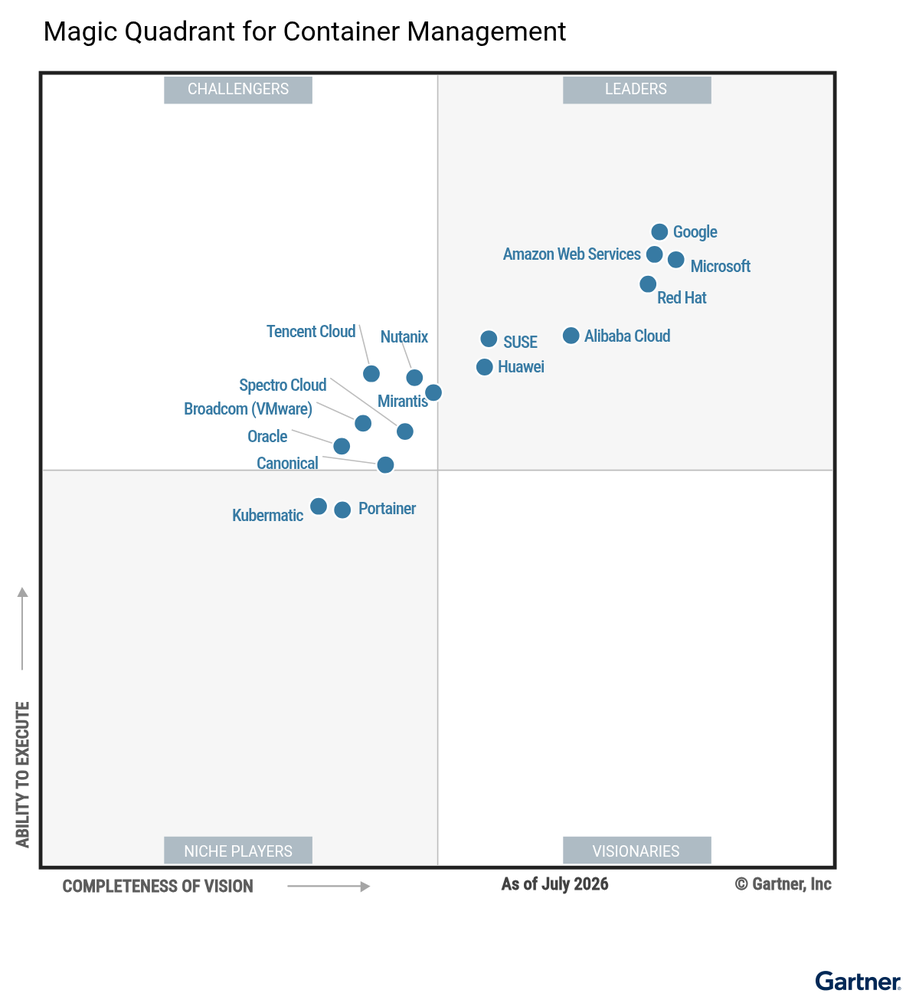
Google is a Leader in the 2026 Gartner Magic Quadrant for Container Management
We’re excited and proud to share that Gartner has recognized Google as a Leader for the fourth year in a row in the 2026 Gartner® Magic Quadrant™ for Container Management, based on its Completeness of Vision and Ability to Execute. Google was positioned highest in Ability to Execute of all vendors evaluated and we believe this validates the success of our mission to deliver a container platform that’s highly optimized for both performance and efficiency. We help global customers to build and run their most demanding and complex workloads at scale, including the next generation of AI and agentic applications.
In the accompanying 2026 Gartner Critical Capabilities for Container Management report, Google Cloud was ranked first in every use case: New Cloud Native Applications, Containerized Existing Applications, AI Training, AI Inference, Edge Applications, and Hybrid Applications.
Gartner predicts1 that “By 2028, 95% of new AI deployments will use Kubernetes, up from less than 30% in 2025.” Containers power today’s most innovative apps and businesses — and deliver the infrastructure customers demand as they transform their businesses in the agentic era.
Google Cloud spearheaded the industry-wide cloud-native revolution when we introduced Kubernetes in 2014 and launched Google Kubernetes Engine (GKE), the world’s first managed Kubernetes service, in 2015. Our commitment to container platforms and the vibrant, innovative Kubernetes ecosystem has only grown stronger and deeper since. Alongside GKE, our serverless container platforms GKE Autopilot and Cloud Run dramatically lower operational costs and help developers deliver amazing containerized apps faster than ever before.
The massive acceleration in enterprise AI has inspired us to redefine infrastructure management for the AI era. In 2026 so far we’ve introduced a wide range of foundational improvements to shift GKE and Cloud Run into agent-native, high-performance platforms designed for autonomous AI systems, massive inference workloads, and secure runtime isolation. Whether you’re training AI at the frontier, launching an AI startup, or leading your enterprise AI transformation, we have the container platform you need. Important highlights include:
Delivering leading performance and efficiency for AI infrastructure
-
GKE predictive latency boost: Built into the GKE Inference Gateway, this ML-driven capability uses capacity-aware routing rather than static configurations to reduce Time-to-First-Token (TTFT) by up to 70%.
-
GKE automatic KV Cache storage tiering: Automatically shifts KV cache data across RAM, Local SSD, and Cloud Storage. This reduces memory bottlenecks, improving TTFT by 40% via RAM offloading and increasing throughput by 70% via Local SSDs for large prompt contexts. [1]
-
GKE accelerated container and model startups: GKE node spin-up times are up to 4x faster, and pod startup speeds have improved by up to 80%. Additionally, native run:AI Model Streamer integration pulls heavy models from Cloud Storage 5x faster.
-
Cloud Run on-demand serverless GPU scale-to-zero: Cloud Run supports NVIDIA RTX PRO 6000 Blackwell GPUs, allowing teams to serve 70B+ parameter models on-demand. Your services can go from zero to a fully provisioned GPU — with all drivers pre-installed — in under 5 seconds. Once active inference or fine-tuning runs complete, Cloud Run automatically scales instances back to zero, eliminating idle infrastructure costs.
Evolving Kubernetes for agentic infrastructure security and scale
-
GKE Agent Substrate: As an open-source, secure-by-default agent execution runtime, Agent Substrate is engineered to run millions of sandboxes with 10x higher density than standard container runtimes. Purpose-built for the era of autonomous agents, Substrate delivers sub-500ms resume operations at over 500 suspend/resume activations per second with a native zero-trust kernel and network isolation. Agent Substrate is available as an open-source solution that runs on any Kubernetes infrastructure and is optimized for GKE.
-
GKE Agent Sandbox: Built on gVisor kernel-isolation technology, Agent Sandbox isolates the host environment from untrusted, multi-agent AI code execution. It provides secure execution at scale, processing up to 300 sandboxes per second with sub-second latency and delivering up to 30% better price-performance when running on Axion processors than comparable hyperscaler cloud providers.
-
GKE Dataplane V2 scalability limits: Architectural capacity bounds for GKE clusters implementing active NetworkPolicies doubled from 7,500 nodes to 15,000 nodes per cluster, supporting the massive infrastructure needs of large enterprise and AI customers.
-
GKE intent-based autoscaling: GKE can now natively autoscale horizontally using application intent and custom metrics beyond basic hardware metrics. This reduces resource allocation reaction times from 25 seconds down to just 5 seconds.
-
Filestore agent volumes: a new offering that attaches and detaches NFS mounts in milliseconds, allowing agents to start/resume near-instantaneously, along with native Read-Write-Many (RWX) access and POSIX-compliant file locking to enable safe multi-agent collaboration without write collisions.
Next-gen developer experience with serverless containers
Whether you’re hosting a standard web API, running a heavy batch data job, processing an asynchronous message queue, or deploying a complex AI agent, Cloud Run handles it all under a single, unified serverless model that delivers an unmatched developer experience and maximum engineering velocity.
-
One-click prototyping in Google AI Studio: You can build and deploy full-stack applications directly within Google AI Studio, making it an exceptional environment for rapid prototyping and experimentation. With a single click, you can instantly package and publish your vibe-coded applications to Cloud Run.
-
Cloud Run instances: This new primitive manages individual, addressable, long-running singleton resources with integrated Cloud Storage volume mounts, allowing persistent background agents like OpenClaw to be deployed cost-effectively. With baseline shared-CPU configurations starting at a highly predictable flat rate of ~$5.70 per month (for 1 vCPU and 1 GiB of RAM), Cloud Run instances delivers an always-on, VM-like experience while bypassing the idle-cost penalties and operational overhead of traditional VMs.
-
Cloud Run sandboxes: Hard-isolated environments spin up in under 500 milliseconds to safely execute untrusted, model-generated code, protecting the host system from unauthorized access.
Take the next steps
As we reach for new heights of performance, security, and scale for our container platforms, we continue to build the future in the open. We invite you to explore Agent Sandbox and Agent Substrate today. We can’t wait to shape the future of agent infrastructure together with our customers and partners. Check out these resources to continue your learning journey:
-
Download your complimentary copy of the 2026 Gartner® Magic Quadrant™ for Container Management.
-
Try Agent Sandbox on GKE.
-
Contribute: Join the Agent Sandbox open-source community.
-
Explore Agent Substrate.
-
Join us at KubeCon North America 2026 in Salt Lake City, November 9-12. For even more fun, arrive a day early for GKE Day on November 9.
-
Discover why Google is also named a Leader in the 2026 Gartner® Magic Quadrant™ for Cloud-Native Application Platforms.
-
Start building the future of serverless applications today at cloud.run.
1. Gartner report: Critical Capabilities for Container Management, 8 September 2026
Gartner, Magic Quadrant for Container Management, Dennis Smith, et al, 2 September 2026
Gartner, Critical Capabilities for Container Management, By Tony Iams, Wataru Katsurashima, Lucas Albuquerque, Dennis Smith, Bhuvie Chhabra, 8 September 2026.
Gartner and Magic Quadrant are trademarks of Gartner, Inc. and/or its affiliates.
Disclaimer: Gartner does not endorse any company, vendor, product or service depicted in its publications, and does not advise technology users to select only those vendors with the highest ratings or other designation. Gartner publications consist of the opinions of Gartner’s business and technology insights organization and should not be construed as statements of fact. Gartner disclaims all warranties, expressed or implied, with respect to this publication, including any warranties of merchantability or fitness for a particular purpose.
