❌

Vue normale

Reçu avant avant-hier

AWS reimagines the getting started experience

16 septembre 2026 à 19:50

Amazon Web Services (AWS) started with a handful of foundational infrastructure services such as Amazon Simple Storage Service (Amazon S3), Amazon Elastic Compute Cloud (Amazon EC2), and Amazon Simple Queue Service (Amazon SQS), so that anyone with an idea could start building. As the world’s largest companies and governments adopted AWS, they asked for features to optimize their configuration for a range of global business contexts, security requirements, and operational needs. To meet these needs, AWS expanded globally through new Regions and added breadth and depth of services in security, networking, governance, and cost controls, so those customers could operate wherever they needed and at the scale they require. That combination of global reach, breadth, and depth remains essential for those customers, but if you are at the start of a new idea, every configuration option is effort standing in the way of shipping your dream product fast.

Today, we’re announcing a new simplified experience on AWS for builders who are working at the pace of AI. Instead of having to complete configuration tasks before you can work on your project, you start with sensible defaults and simple administration. You sign up using an existing identity from providers including Google, GitHub, and Apple. For most new customers, no credit card is required to start and you receive $100 in free credits as part of the AWS Free Tier. You can build immediately in your first project. As you continue to work, you can invite collaborators with just an email address, without learning about AWS Identity and Access Management (IAM) or AWS IAM Identity Center. When your project grows beyond the free credits, you can set a spend limit so you stay within your budget on the paid plan. If you grow to need additional customization, you can activate advanced AWS features to access the full breadth and depth of AWS without migrating.

How it works
When you sign up, AWS organizes your work in a project. A project contains an AWS account, where you create resources, and settings for sharing with team members. AWS creates that structure for you and applies additional security controls so you can start building your idea. After signing in, you get a prompt to paste into your coding agent that configures it to work with your new AWS environment. From there, your agent can deploy resources, run workloads, and iterate on your application following best practices for working with AWS.

You can create another project with a click. When you want to work with an additional team member, you send an invitation to their email address. Identity permissions are handled for you, so there are no IAM users to create; each person you invite only gets access to the projects you specify. Console workflows and coding agents also configure permissions between supported services and resources automatically, so you do not have to set up or troubleshoot resource permissions by hand.

When you’re ready to move beyond free credits, you can upgrade to a paid plan by entering your payment method. You can set a monthly spend limit on a project based on your usage trends, starting at $20 per month. The spend limit is the ceiling for that project’s costs, and you pay for what you actually use up to that amount. For example, if you set a $50 spend limit and your project incurs $32 in charges that month, you pay $32 (plus taxes). AWS will suggest a spend limit based on your usage, and you can accept that recommendation or set a custom amount if you are planning to further scale your usage. If your project approaches the limit, you first receive notifications. If spend reaches the limit, AWS pauses your project rather than accumulating charges, and you can resume working on it when you raise the limit. Each project has its own spend limit so you can give a larger budget to a workload that is gaining traction while keeping a smaller budget on an experimental idea.

Let’s try it out
To get started, I went to aws.amazon.com and chose Create account. I signed in with my Google account and within seconds had a new project ready to go, as shown in the following screenshot.

The Sign up for AWS page, with options to continue with email or sign in using Google, GitHub, Apple, or Amazon.

The first thing I saw was a prompt to configure my coding agent. I copied the prompt and pasted it into my agent. The agent set up the AWS Command Line Interface (AWS CLI) and the Agent Toolkit for AWS, logged me into AWS, and created a CLAUDE.md file in my project with guidance for the new experience.

The Setup Agent Toolkit for AWS dialog, with a prompt to copy and paste into your coding agent.

With the agent connected, I gave it a short prompt: build an API that returns a new unique sequential ID on every request. The agent created an AWS Lambda function, an Amazon DynamoDB table, and an Amazon API Gateway API, then deployed them for me. I did not have to configure resource permissions by hand. Within a few minutes I had a public endpoint that returned a newly minted ID on each request. My project started with $100 in free credits, and I received an additional $20 when the Lambda function was deployed.

A coding agent prompt to build an API that returns a unique sequential ID on every request.

The coding agent presents architecture options for the sequential ID API, with AWS Lambda and Amazon DynamoDB selected.

The coding agent confirms the API is live and lists the Amazon DynamoDB table, AWS Lambda function, and Amazon API Gateway API it deployed.

From the project, I could manage settings, invite team members by email, and monitor billing, as shown in the following screenshots.

The Projects page, showing remaining free-plan days, credits, and a project.

The project Members page, with the option to invite a new team member by email.

The Billing page, showing a $0.00 balance on the free plan, remaining credits, and cost by project.

Activating advanced features
If you reach the point where you need multiple Regions, or governance features like custom policies in AWS Organizations, you can activate advanced features at no additional cost. You’ll find yourself in a fully configured AWS Organization built according to best practices, with no migration and no downtime. Everything you configured previously is preserved and reflected in the underlying AWS services.

Now rolling out
We’ve heard from builders that they do not want to spend their first hours configuring an AWS environment. They want to build what they came to build, and we listened. AWS began as a place where anyone with an idea could start building, and this new simplified experience brings that starting point back, with sensible defaults so you can begin immediately, and with the global reach, breadth, and depth of AWS still there when your idea needs it. We are gradually rolling this experience out to new customers. We cannot wait to see what you build, and we want your feedback on the experience.

To try the new experience, create a new AWS account. To learn more, see the AWS Sign up user documentation.
Amazon EC2 R9g and R9gd instances powered by AWS Graviton5 processors are now generally available

31 août 2026 à 21:53

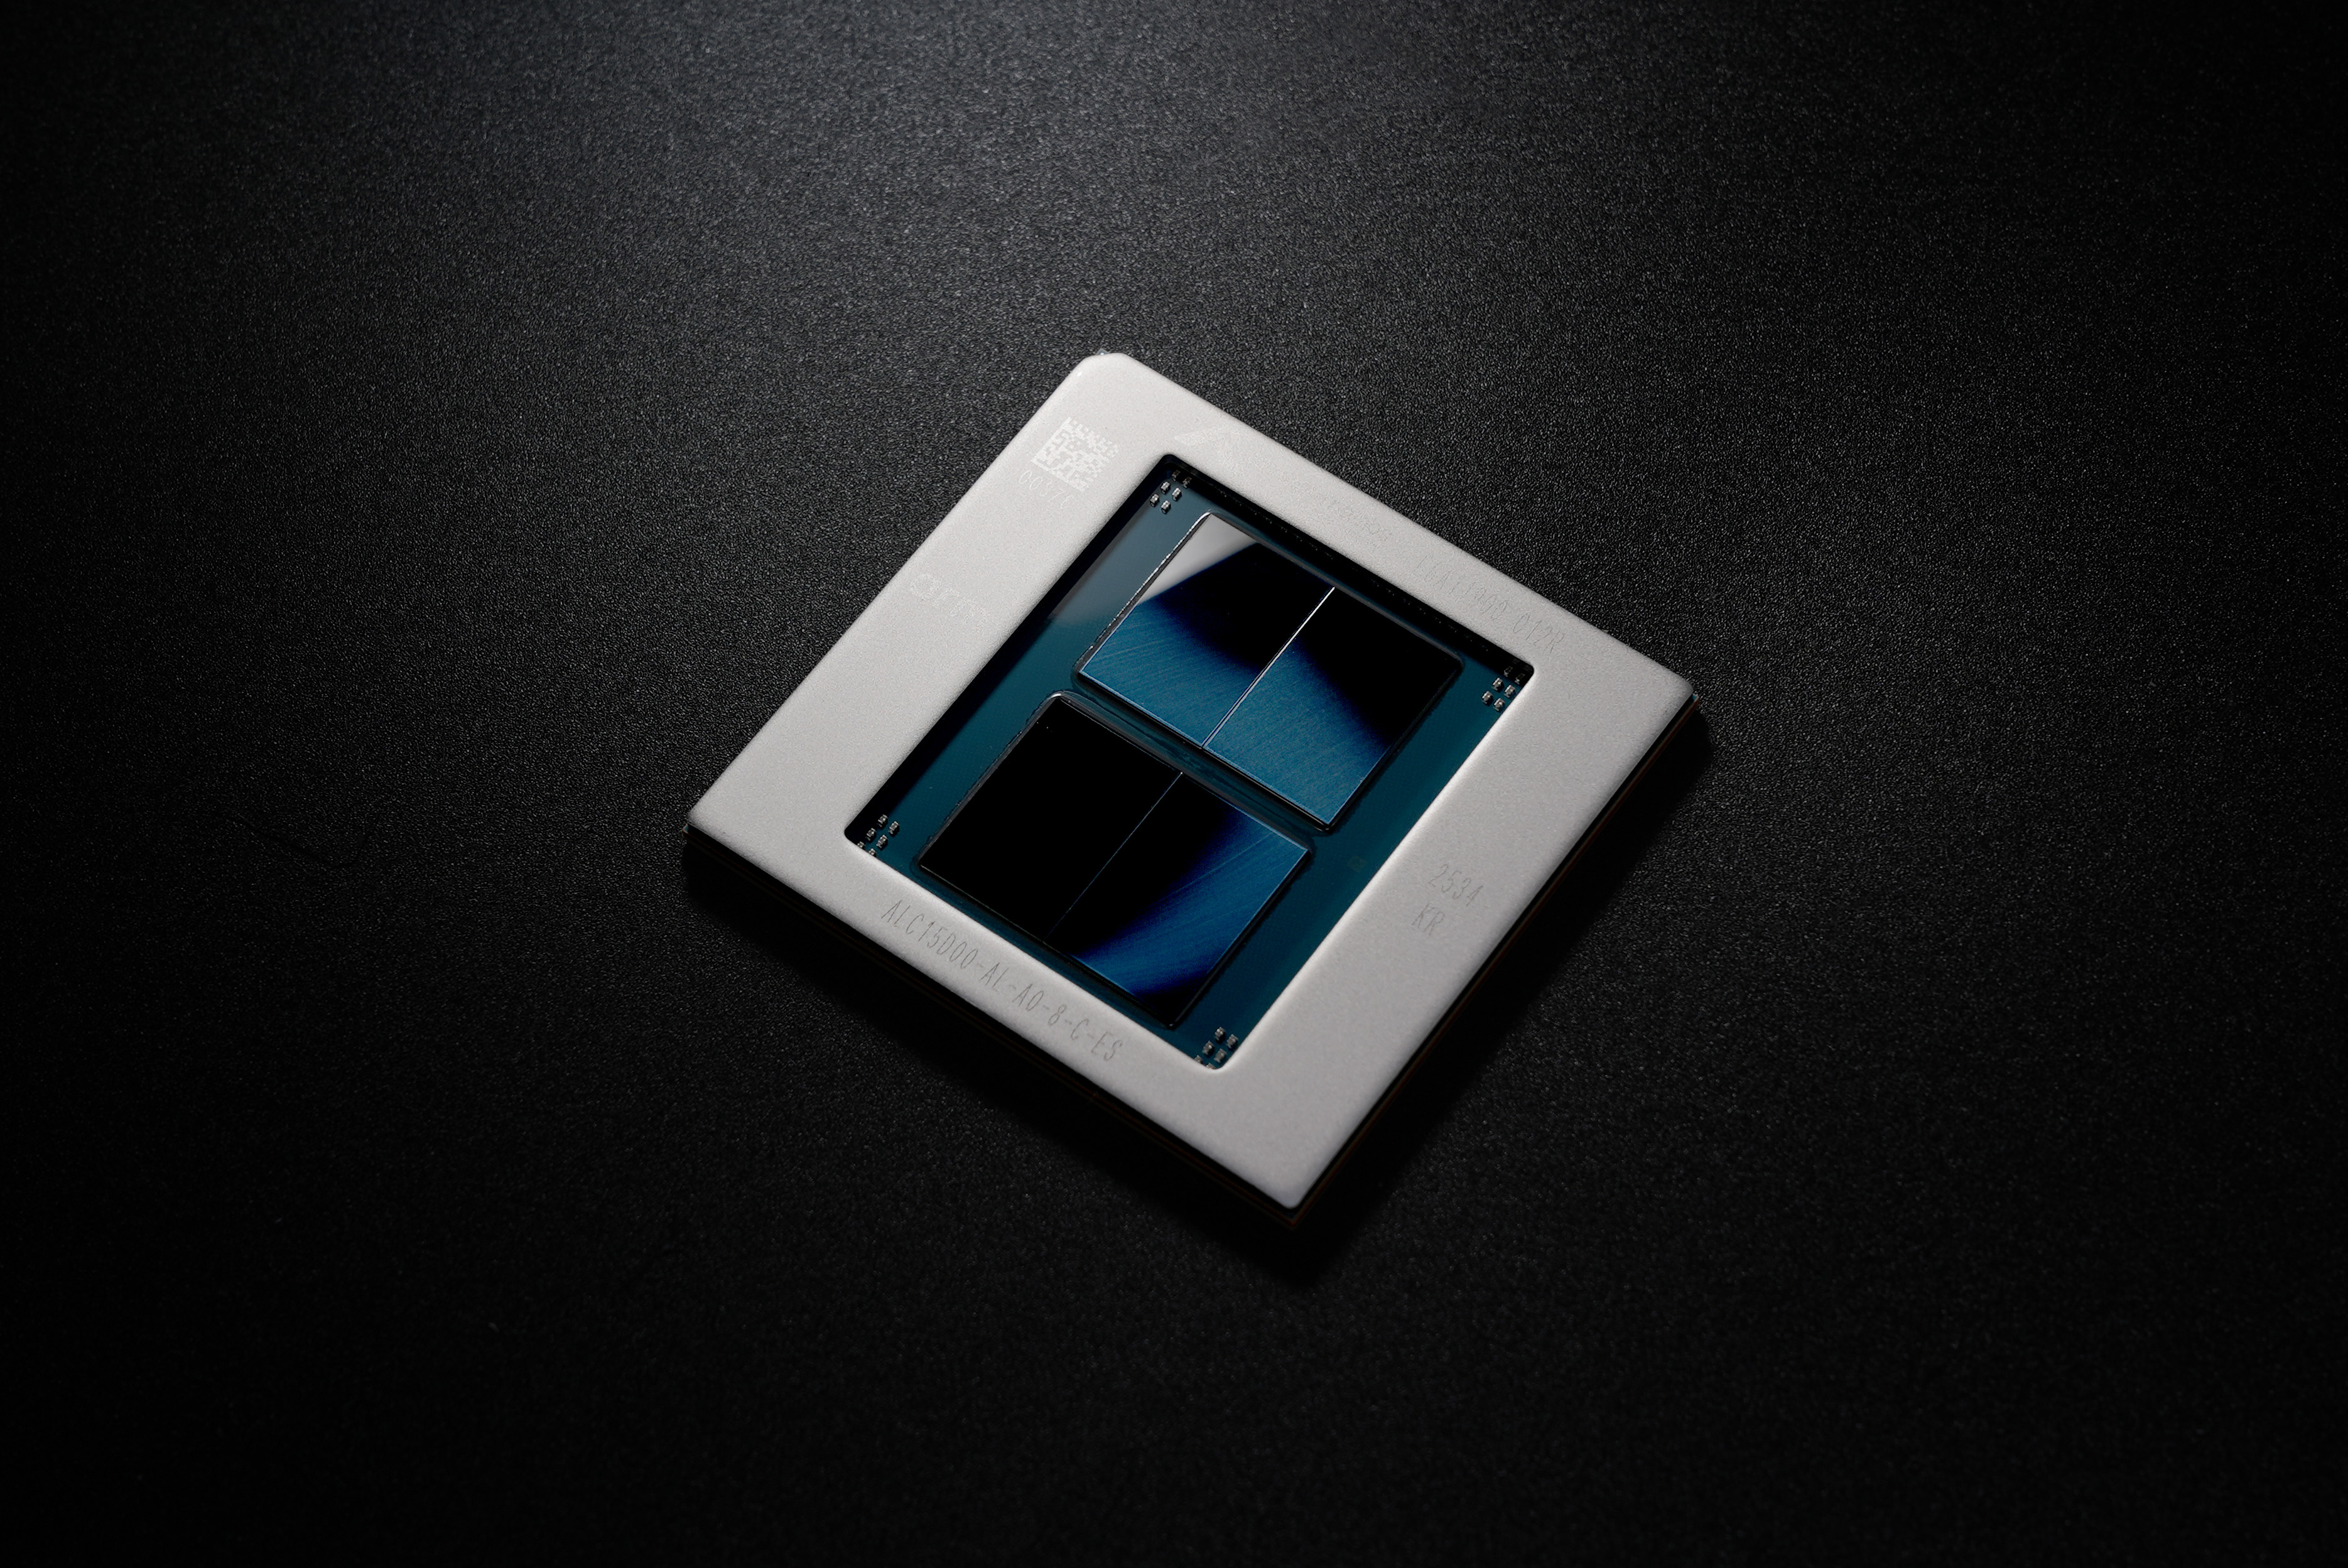
Today, Amazon EC2 R9g and R9gd instances are generally available, powered by AWS Graviton5 processors. R9g instances are memory-optimized and deliver up to 25% better compute performance compared to Graviton4-based R8g instances, powered by the most energy efficient processor AWS has ever built.

R9g instances are ideal for memory-intensive workloads including databases, in-memory caches (Valkey, Redis, MemCached), real-time big data analytics, Linux-based workloads including containerized and micro-service-based applications (e.g. Kubernetes, Docker, EKS, ECS), as well as applications written in popular programming languages such as C/C++, Rust, Go, Java, Python, .NET Core, Node.js, Ruby, and PHP.

R9gd instances include local NVMe-based SSD block-level storage, ideal for memory-intensive workloads requiring fast, low-latency local storage such as open-source databases, distributed real-time big data analytics, large in-memory databases, and large caching workloads.

If you’re running workloads on R8g instances today, R9g gives you more performance per vCPU with faster memory, higher network and Amazon EBS bandwidth, and a larger L3 cache, all while using less energy.

What makes R9g different
Graviton5 processors bring several hardware improvements over Graviton4:

  • Up to 25% higher compute performance per vCPU
  • DDR5 8800 MT/s memory (up from 5600 MT/s in Graviton4), the fastest memory available in the cloud
  • 5x larger L3 cache for better data locality
  • Up to 2x higher network and EBS bandwidth for the largest instance sizes (up to 100 Gbps network, up to 72 Gbps EBS on the 48xlarge)
  • Up to 3x higher packet-processing performance

R9g and R9gd instances support Instance Bandwidth Configuration (IBC), which lets you adjust the allocation of bandwidth between Amazon EBS and Amazon VPC networking by 25%. This helps optimize performance for workloads with specific bandwidth requirements such as databases and caching.

All R9g and R9gd instances run on the AWS Nitro System, which offloads virtualization, storage, and networking to dedicated hardware. This gives your applications near-bare-metal performance while maintaining strong security isolation between instances.

R9g and R9gd instances feature the Nitro Isolation Engine (NIE), the same enhancement to the Nitro System introduced with C9g and M9g instances earlier this year, which enforces isolation of instances and harnesses formal verification to provide assurances of isolation with mathematical precision. Nitro Isolation Engine is a purpose-built component that is responsible for enforcing isolation between virtual machines, including mediation of all access to virtual machine memory, CPU register state, and I/O devices through a minimal set of APIs. Nitro Isolation Engine leverages formal verification, a technique to mathematically demonstrate that the hardware or software behaves as intended, and not just in specific test cases. This intensive verification technique establishes Nitro as the first formally verified cloud hypervisor, pioneering a new standard for mathematically proven cloud security. To learn more about the Nitro Isolation Engine, visit the blog post. For details on the formal verification results, including scope and assumptions, see the technical white paper.

EC2 R9g and R9gd instance specifications
R9g and R9gd instances are each available in 11 sizes, from medium to metal-48xl. The following tables show the full specifications for each size.

Instance size vCPUs Memory (GiB) Instance Storage Network Bandwidth (Gbps) EBS Bandwidth (Gbps)
r9g.medium 1 8 EBS-Only Up to 15 Up to 12
r9g.large 2 16 EBS-Only Up to 15 Up to 12
r9g.xlarge 4 32 EBS-Only Up to 15 Up to 12
r9g.2xlarge 8 64 EBS-Only Up to 17 Up to 12
r9g.4xlarge 16 128 EBS-Only Up to 17 Up to 12
r9g.8xlarge 32 256 EBS-Only 17 12
r9g.12xlarge 48 384 EBS-Only 25 18
r9g.16xlarge 64 512 EBS-Only 34 24
r9g.24xlarge 96 768 EBS-Only 50 36
r9g.48xlarge 192 1536 EBS-Only 100 72
r9g.metal‑48xl 192 1536 EBS-Only 100 72

R9gd instances offer the same compute and networking performance as R9g, with the addition of local NVMe-based SSD storage for workloads that need fast, low-latency scratch space or temporary caches.

Instance size vCPUs Memory (GiB) Instance Storage (NVMe SSD) Network Bandwidth (Gbps) EBS Bandwidth (Gbps)
r9gd.medium 1 8 1 x 59 GB Up to 15 Up to 12
r9gd.large 2 16 1 x 118 GB Up to 15 Up to 12
r9gd.xlarge 4 32 1 x 237 GB Up to 15 Up to 12
r9gd.2xlarge 8 64 1 x 474 GB Up to 17 Up to 12
r9gd.4xlarge 16 128 1 x 950 GB Up to 17 Up to 12
r9gd.8xlarge 32 256 1 x 1900 GB 17 12
r9gd.12xlarge 48 384 3 x 950 GB 25 18
r9gd.16xlarge 64 512 1 x 3800 GB 34 24
r9gd.24xlarge 96 768 3 x 1900 GB 50 36
r9gd.48xlarge 192 1536 3 x 3800 GB 100 72
r9gd.metal‑48xl 192 1536 3 x 3800 GB 100 72

Getting started
You can launch R9g and R9gd instances from the Amazon EC2 console using any supported Arm-based AMI. R9g instances support Amazon Linux 2023, Amazon Linux 2, Ubuntu 22.04+, RHEL 8.4+, SUSE Linux Enterprise Server 15 SP3+, Debian 12+, and other major Linux distributions.

If you’re migrating from R8g, no code changes are required for most applications. Select the equivalent R9g instance size and your application runs with better performance. For containerized workloads, R9g works with Amazon EKS, Amazon ECS, and standard Kubernetes deployments. Multi-arch container images built for Arm64 run without changes.

Several resources help you get started: the AWS Graviton Getting Started Guide covers how to build, run, and optimize workloads on Graviton-based instances. The Graviton Savings Dashboard helps you track cost savings. AWS Transform automates code transformations for migrating Java applications from x86 to Graviton. To learn more, visit AWS Graviton Processors or Level up your compute with AWS Graviton.

Pricing and availability
Amazon EC2 R9g and R9gd instances are available in US East (N. Virginia, Ohio), US West (Oregon), and Europe (Frankfurt) Regions.

R9g and R9gd instances are available for purchase through Savings Plans, On-Demand, Spot Instances, Dedicated Instances, or Dedicated Hosts. For detailed pricing, visit the Amazon EC2 pricing page.

Ready to get started? Launch R9g instances from the Amazon EC2 console. For more details, visit the Amazon EC2 R9g instances page.

If you want to call APIs, search documentation, find regional availability, and check troubleshooting about this feature, try using the AWS MCP Server and plugins with your preferred AI tool. Share your feedback on AWS re:Post for Amazon EC2 or reach out through your usual AWS Support contacts.

— Daniel Abib

AWS Weekly Roundup: Welcome DuckLabs to the team, Agentic Resource Discovery (ARD), and more (August 31, 2026)

31 août 2026 à 16:45

The news that interested me the most last week was the DuckLabs acquisition. AWS has signed a definitive agreement to acquire DuckLabs, the Amsterdam-based company behind DuckDB, the popular open source analytical database that runs in-process and executes SQL directly against files like Parquet, CSV, and JSON. DuckDB stays open source under its independent foundation and the MIT license, and over time AWS plans to combine its speed at everyday queries with the enterprise scale of services like Amazon S3, Amazon Redshift, and Amazon Athena.

Co-founded by Hannes Mühleisen and Mark Raasveldt, DuckDB runs locally or on Amazon S3, which makes it remarkably fast for the everyday queries (a terabyte or less) that make up the bulk of real-world analytics. It also happens to pair beautifully with AI agents, which “poke” and experiment their way through data much like humans do. The co-founders will continue leading its technical direction while AWS combines DuckDB’s speed with analytics services like Amazon EMR, AWS Glue, and Amazon SageMaker. For the bigger picture on why this matters, Andy Warfield, Vice President and Distinguished Engineer shared his thoughts on the post DuckDB and the changing physics of analytics on All Things Distributed.

Now, let’s get into this week’s AWS news…

Last week’s launches
Here are some launches and updates from this past week that caught my attention:

  • Amazon ECS now automatically detects and recovers container instances that lose agent connectivity – Amazon ECS now continuously monitors agent connectivity to the control plane and surfaces a new AGENT_CONNECTIVITY health event across AWS Fargate, Amazon ECS Managed Instances, and Amazon ECS on EC2. On Fargate and Managed Instances, ECS handles recovery automatically, draining tasks, launching replacements, and deregistering the impaired instance. On EC2, you can wire the event into your own workflow. Available at no additional cost in all AWS Commercial and AWS GovCloud (US) Regions.
  • AWS Lambda introduces public preview runtimes, starting with Node.js 26 and Python 3.15 – You can now test upcoming Lambda runtimes before they reach general availability. Preview runtimes use the same identifier as the eventual GA version, so your functions graduate automatically with no action required. Third-party tools and deployment frameworks can also validate compatibility ahead of GA. Not meant for production yet (breaking changes are possible), but a great way to get ahead of your next upgrade. Available in all AWS commercial, AWS GovCloud (US), and China Regions.
  • AWS IoT Core adds a native InfluxDB rule action – You can now route time-series data from your IoT devices straight into InfluxDB (Amazon Timestream-managed or self-hosted) without writing custom code or standing up an intermediate service. IoT Core formats data into InfluxDB’s line protocol and supports device-side and server-side batching. Available in all AWS Regions where Amazon Timestream for InfluxDB is offered.
  • Amazon GameLift Servers now includes enhanced DDoS protection – Your game servers now get automatic protection against network and transport layer (layers 3 and 4) DDoS attacks – UDP reflection, SYN floods, and similar vectors – with nothing to enable or opt into. Built on top of AWS Shield Standard with gaming-optimized traffic shaping, it turns on the moment your servers start running (Server SDK 5) at no extra cost. It’s available in all supported GameLift Servers Regions except China (Beijing) and China (Ningxia).
  • Amazon SageMaker HyperPod expands support for Ray – You can now run Ray workloads on SageMaker HyperPod with built-in observability, resilient training, and accelerated inference. Create and manage Ray clusters from Amazon SageMaker Studio, attach JupyterLab or your local IDE so a multi-node cluster behaves like a local dev environment, and get auto-provisioned Grafana dashboards. Node auto recovery, hung job detection, and tiered checkpointing keep large training runs healthy, while Ray Serve adds a tiered KV cache for inference. Your existing open source Ray code runs unchanged. Available for HyperPod clusters orchestrated by Amazon EKS.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Other AWS news
Here are some additional posts and resources that you might find interesting:

  • Happy 20th birthday, Amazon EC2! – Amazon EC2 turns 20. Channy Yun looks back at how EC2 grew from a single m1.small instance type in one Region to more than 1,200 instance types across 39 Regions, along with the custom silicon journey from the first Graviton to Graviton5 and Trainium3. A fun and worthwhile read on the service that still underpins so much of AWS – including Amazon ECS, Amazon EKS, AWS Lambda, Amazon SageMaker, and Amazon Bedrock.
  • Agentic Resource Discovery (ARD): an open specification for agent discovery – As organizations scale up agents, tools, and MCP servers, those resources end up scattered across clouds, on-premises infrastructure, and SaaS platforms – each with its own registry and metadata. ARD is a new open specification (Apache 2.0) that defines a common way to describe and discover agentic resources, so publishers “describe once” and consumers “discover everywhere” – think DNS, but for agents. AWS contributed feedback but doesn’t own the spec, and it complements the AWS Agent Registry by letting you federate across catalogs without migrating.
  • Get started with the Agent Toolkit for AWS in the AWS CLI – A single AWS CLI command (aws configure agent-toolkit) now equips AI coding agents like Kiro, Claude Code, Codex, and Cursor with curated, up-to-date AWS knowledge and a secure connection to thousands of AWS APIs through the AWS MCP Server. If you build with an AI coding assistant, this helps it choose the right services, use modern APIs, and follow security best practices – so it gets AWS code right more often the first time.

Upcoming AWS events
Check your calendar and sign up for upcoming AWS events:

  • AWS Summits – Free in-person events where builders come together to learn, connect, and explore the latest in cloud and AI. Upcoming stops include Zurich (September 2), São Paulo (September 3), Tel Aviv (September 10), and Dubai (September 30). Can’t attend in person? You can stream sessions through the Global Livestream and On-Demand Hub. I’ll be presenting two sessions on generative AI and Amazon Bedrock at the São Paulo Summit – if you’re there, come say hello.
  • AWS Community Days – Community-led conferences where content is planned, sourced, and delivered by community leaders. Upcoming events include JAWS SONIC 2026 in Tokyo (September 5) and Warsaw, Poland (September 8).

Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development. Browse here for upcoming AWS-led in-person and virtual events and developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Daniel Abib

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

AWS Weekly Roundup: Student Rewards on AWS Builder Center, Local Zone in Las Vegas, and more (August 24, 2026)

24 août 2026 à 18:20

During my time at AWS, I have always looked for opportunities to work with students. I have delivered over 50 talks at universities across the region, and watching the potential in the room is always a strong motivator. It reminds me of why I do this work, and that the students I meet today may well become our customers and collaborators tomorrow. That is why I am happy to open this week with Student Rewards on AWS Builder Center.

Rick Suttles published Introducing Student Rewards on AWS Builder Center, a new benefit for verified higher education students. When you verify your enrollment through SheerID and complete your Builder Center profile, you unlock 12 months of premium AWS Skill Builder access (900+ courses, hands-on labs, certification exam prep, and game-based learning). From there, you earn badges through actions on Builder Center: publishing articles, commenting, and maintaining engagement. At 7 badges, you unlock $10 in AWS Credits. At 14 badges, another $20 in credits. At 21 badges, you earn an AWS Foundational Certification exam voucher ($100 value).

This represents a commitment of over $500 million in resources during this back-to-school season, providing students with the training, tools, and certification needed to start building their careers in cloud and AI. Student Rewards is available to students 18 years or older and enrolled at accredited higher education institutions worldwide, subject to verification and applicable terms.

Verify your student status and start learning, earning badges, and unlocking rewards!

Last week’s launches
Here’s what else happened this week.

  • A new AWS Local Zone in Las Vegas, Nevada – This new Local Zone supports Amazon EC2 C7i, M7i, R7i, and C8gn instances, Amazon EBS, Amazon ECS, Amazon EKS, Application Load Balancer, and AWS Direct Connect. AWS Local Zones are now available in more than 30 metropolitan areas worldwide. In addition, AWS added a fourth Availability Zone to the Europe (London) Region, delivering next-generation AI and ML capacity with Trn3 and P6 accelerated instances alongside general-purpose compute.
  • Amazon EC2 Auto Scaling now supports batch instance termination – You can now pass up to 100 instance IDs to the TerminateInstanceInAutoScalingGroup API to terminate them as a batch, reducing the number of API calls needed to scale down your Auto Scaling groups. Batch termination is designed for workloads that need to rapidly scale down, such as AI/ML training jobs, container orchestrators, or event-driven architectures that spin up large fleets temporarily.
  • AWS CloudShell now includes a built-in visual file editor – CloudShell now includes a visual file editor that you can launch directly from your shell session using a single edit command. The editor supports syntax highlighting, find-and-replace, multi-line selection, copy-paste, and undo-redo in a single browser session. Whether you are updating a deployment script, modifying an agent steering file, editing a CloudFormation template, or fixing a Lambda function, the editor provides a seamless edit-and-run experience without leaving CloudShell.
  • Amazon Bedrock now supports SpaceXAI Grok 4.6 with cross-Region inference – Grok 4.6, a frontier model built for coding, agentic tasks, and knowledge work, is now available on Amazon Bedrock. The model runs on the bedrock-runtime endpoint with support for the Responses, Chat Completions, and Converse APIs, and works with existing account-level controls including model invocation logging, Amazon CloudWatch metrics, and cost itemization in AWS Cost Explorer.
  • Amazon Bedrock expands API support and introduces cross-Region inference for OpenAI models – Amazon Bedrock now supports OpenAI GPT-5.6 models (Sol, Terra, and Luna) with the Responses, Converse, and Chat Completions APIs, and adds cross-Region inference. Geo cross-Region inference routes requests within a predefined geography (including new US Geo support with this launch), while Global cross-Region inference serves requests from any commercial AWS Region at a lower per-token cost.
  • AgentCore payments is now generally available in Amazon Bedrock AgentCore – At general availability, AgentCore payments includes Quick Create for Coinbase credential provisioning directly within the AgentCore console, a curated Coinbase Bazar MCP server of pay-per-use x402 endpoints via AgentCore gateway, support for the Machine Payment Protocol (MPP), and the “upto” scheme in the x402 protocol for pay-per-inference and dynamic pricing use cases. To learn more, visit the AI Blog post.
  • AWS Glue 6.0 delivers 30% price reduction and Iceberg v3 support – AWS Glue 6.0 is built on a fully modernized runtime, Apache Spark 4.1, Python 3.13, and Scala 2.13, delivering 30% lower pricing than previous AWS Glue versions. With Iceberg v3, Glue 6.0 adds the VARIANT data type with automatic shredding for faster reads on semi-structured data, deletion vectors for high-performance row-level updates, geometry and geography data types for spatial processing, and flexible schema evolution.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Other AWS news
Here are some additional posts you may find useful:

  • Updates to your AWS Sign-In experience – AWS is gradually introducing updates to the sign-in and sign-up experience. The redesigned sign-in page introduces a unified email entry point for root users and customers using the new email-based sign-in method, while IAM users continue signing in with their account ID, username, and password. The page also includes sign-in options for customers whose AWS account was created using a supported identity provider (Google, GitHub, Apple, or Amazon.com). A redesigned session selection page simplifies viewing and managing multiple active account and role sessions. If your organization relies on browser automation or scripted workflows that interact with the sign-in page, review the post to understand how these changes might affect your configuration.
  • In the works: AWS Builder Lofts in Berlin, Hyderabad, and São Paulo – My colleague Channy announced plans to open new Builder Lofts in three cities. Since the first Builder Loft opened in San Francisco in July 2025, it has welcomed more than 22,500 developers through its doors. Each new location will be a permanent community space offering free workshops, networking events, pitch nights, content creation spaces, and co-working areas. Berlin will focus on digital sovereignty and security-readiness, Hyderabad on AI and cloud-native architecture, and São Paulo on supporting Latin America’s developer ecosystem.
  • AWS and Amazon WorkSpaces recognized as a Leader in the 2026 Gartner Magic Quadrant for Desktop as a Service – AWS has been named a Leader in the 2026 Gartner Magic Quadrant for Desktop as a Service (DaaS) for the third consecutive year, evaluated on Completeness of Vision and Ability to Execute. Gartner noted strengths in operations, geographic strategy, and overall viability. This is also the first year the evaluation includes Amazon WorkSpaces for AI agents, a capability that runs AI agents within the same desktop environment, security perimeter, and audit trail as human users.

For a full list of AWS blog posts, be sure to keep an eye on the AWS Blogs page.

Upcoming AWS events
Check your calendar and sign up for upcoming AWS events:

Visit the AWS Builder Center to meet other builders, contribute solutions, and find resources that help you keep building.

Summer is slowly coming to an end, and I am already planning a few days off in the coming months to keep me motivated through the rainy autumn ahead. I hope you are doing the same. Come back next week for more!

— Esra

Amazon DynamoDB now supports real-time vector search at any scale

5 août 2026 à 16:45

Today, we’re announcing the general availability of vector search in Amazon DynamoDB. You can now store vector embeddings alongside your operational data in DynamoDB and run similarity searches directly against that data, without replicating it to a separate vector store.

DynamoDB supports native vector search with single-digit millisecond latency at 99%+ recall, and is designed for any scale, even trillions of vectors. There are no servers to provision, patch, or manage, and no software to install, maintain, or operate. The service has no versions, no maintenance windows, and zero downtime maintenance.

Vector indexes have no storage limits and scale horizontally as your data grows. You can now build applications that require semantic retrieval on agentic memory, retrieval augmented generation, recommendation engines, personalized experiences, anomaly detection, and more using DynamoDB and its native vector search.

If your application already uses DynamoDB, adding vector search previously required copying data into a dedicated vector database while maintaining a synchronization pipeline between the two services. This added operational overhead, data movement costs, licensing costs, and the challenge of maintaining predictable low latency at scale. With vector search built into DynamoDB, your vectors and operational data share the same serverless infrastructure and the same pay-per-request pricing model.

Vector search in DynamoDB introduces a new index type that you create on an attribute storing vector embeddings. You generate embeddings using a model of your choice, such as Amazon Bedrock Titan Text Embeddings, Cohere Embed, or OpenAI text embedding models, and store them as a list of floats in your table using a standard PutItem call. You then create a vector index on that attribute and specify the number of dimensions, the distance function, and any non-vector attributes you want to use as filters to narrow search results at query time. The SearchVectors API accepts a query vector, the number of results to return (up to 100), and optional filter conditions. It returns results ranked by similarity.

Use vector search in DynamoDB when your operational data already lives in DynamoDB and you want to add similarity search without provisioning a separate database or managing a synchronization pipeline. DynamoDB is fully serverless, so vector search scales automatically with no infrastructure to manage. It supports up to 4096 dimensions, Euclidean, Cosine, and Dot product distance functions, and inline filtering.

Getting started with vector search in DynamoDB
This walkthrough shows how to add vector search to an existing DynamoDB table using the DynamoDB console. The scenario contains an online sporting goods store with a product catalog table. Each item has standard operational attributes such as productId, category, description, marketplace, name, and price. The goal is to add semantic search so shoppers can find products using natural language queries rather than exact keyword matches.

1. Prepare DynamoDB table
To enable semantic search, I first generate vector embeddings for the product descriptions already in my table. Embeddings are numerical representations of text generated by a machine learning model that capture the meaning of the content. Two items with similar descriptions will have embeddings that are close to each other in vector space, which is what makes similarity search possible.

I can generate embeddings using Amazon Bedrock Titan Text Embeddings or another embedding model, then add them to my table using the AWS Management Console, AWS Command Line Interface (AWS CLI), AWS SDKs, AWS CloudFormation, or other infrastructure-as-code (IaC) tools.

For an existing table like ProductCatalog, I add the embeddings to each item as a new attribute named descriptionEmbedding using an UpdateItem call. DynamoDB stores vector embeddings using its existing List data type. Each element in the list is a Number that represents a single float value of the embedding vector. This means I do not need a new data type or schema change to start storing vectors alongside my existing operational attributes.

2. Create vector index
In the DynamoDB console, open the ProductCatalog table and choose the Indexes tab. I choose Create vector index. On the Create vector index page, I fill in the index details as follows. I enter ProductDescriptionIndex as the Index name and descriptionEmbedding as the Vector attribute.

I enter the number of Dimensions that matches my embedding model’s output and select Cosine as the Distance function. Cosine measures the angle between vectors rather than their magnitude, which makes it effective for comparing semantic similarity of text embeddings. Vector search in DynamoDB also supports Euclidean and Dot product distance functions.

  • Euclidean: Use when the magnitude of the vectors is meaningful, such as clustering items by a numeric value like purchase count.
  • Dot product: Use when both direction and magnitude matter, such as in recommendation systems that weight interest alignment and frequency together. As a general rule, match the distance function to the one used to train your embedding model for the best accuracy.

I enter marketplace as the Partition key. The vector index partition key controls how DynamoDB distributes vectors across partitions, allowing the index to scale out while maintaining predictable latencies. Each search is scoped to a single partition key value, so a product catalog serving multiple marketplaces can search within one marketplace’s inventory without scanning the entire index. The partition key is optional, but recommended for large datasets with high query throughput.

I expand Inline filter attributes and add category as a filter attribute. This helps me narrow search results to a specific product category at query time. Filter conditions support exact-match values only; range conditions such as BETWEEN or BEGINS_WITH are not supported. I leave Attribute projections set to All so that all table attributes are returned with my search results. Choose Create vector index and wait for the index status to change to Active.

3. Run vector search
I generate a query vector from a natural language search term such as “lightweight running shoes for summer” using the same embedding model I used for the product descriptions. In the DynamoDB console, I choose Explore items in the left navigation pane and select the ProductCatalog table.

Choose Search to switch to vector search mode. I select ProductDescriptionIndex from the Select a vector index dropdown, paste the query vector into the Search vector field, and set Number of results (Top K) to 5. I enter US as the Partition key value to scope the search to the US marketplace. I expand Inline filter attributes and set category equal to footwear to narrow the search to footwear products only. Now, choose Run.

DynamoDB returns the five most semantically similar products in the footwear category, ranked by similarity score, alongside the standard operational attributes such as name and price in the same response. The similarity score’s meaning depends on the distance function selected for the index. For Cosine and Euclidean distance functions, lower similarity score values indicate higher similarity, with a score of 0 indicating identical vectors. For the dot product distance function, higher similarity score values indicate higher similarity.

To interact with vector search programmatically, including calling APIs and searching documentation, try the AWS MCP Server and plugins with your preferred AI coding tool. To learn more, visit the Amazon DynamoDB Developer Guide.

Get started today
Vector search in Amazon DynamoDB is generally available in all commercial AWS Regions, including the AWS GovCloud (US) Regions. For Regional availability and a future roadmap, visit the AWS Capabilities by Region. For pricing details, visit the Amazon DynamoDB pricing page.

Start exploring vector search in DynamoDB today and send feedback to AWS re:Post for Amazon DynamoDB or through your usual AWS Support contacts.

— Esra

AWS Weekly Roundup: Local Zone in Athens, Claude Opus 5 on AWS, Lambda durable execution for .NET, and more (July 27, 2026)

27 juillet 2026 à 16:54

Last week I had the privilege of spending three days in São Paulo with technical builders from across Latin America, brought together for a regional tech event full of deep-dive sessions, hands-on workshops, and conversations with customers and partners. What struck me most wasn’t any single session, it was the energy of a technical community that so rarely gets to be in the same room. People traded architecture ideas over coffee, sketched out solutions on whiteboards, and left with a longer list of things to try than they arrived with. It’s a good reminder that, for all the tooling we build, the community around it is what makes the technology stick.

That community spirit connects nicely to the week’s biggest infrastructure news, which is all about bringing AWS closer to where builders actually are.

Now, let’s get into this week’s AWS news…

Headlines
AWS Local Zone in Athens, Greece: AWS has opened a new Local Zone in Athens, Greece, the second Local Zone in EMEA with support for Amazon S3 and Amazon EBS Local Snapshots, so you can store and process data within Greece to help meet local data residency requirements. The Athens Local Zone supports Amazon EC2 (C7i, M7i, and R7i instances), Amazon S3 with the One Zone-Infrequent Access storage class, Amazon EBS, Amazon ECS, and more.

Athens, Greece skyline

With this launch, you can process and store data in-country while delivering single-digit millisecond latency to your end users. AWS Local Zones place AWS infrastructure much closer to large population and industry hubs to support workloads such as financial services, healthcare, media production, and real-time gaming. For builders in Greece, this means running latency-sensitive workloads locally and meeting in-country data residency requirements, without managing your own data center infrastructure. To learn more, visit AWS Global Infrastructure and Sustainability Blog post.

Last week’s launches
Here are some launches and updates from this past week that caught my attention:

  • Claude Opus 5 on AWS: You can use Anthropic’s Claude Opus 5, the most advanced Opus model yet, matching Claude Fable 5’s top-tier intelligence in many domains at Opus-tier pricing. Amazon Bedrock offers Claude Opus 5 with zero data retention (ZDR) enabled by default, giving you Opus’ top-tier intelligence while meeting your data governance requirements unlike Claude Fable 5. You have two ways to access Claude Opus 5: Amazon Bedrock and Claude Platform on AWS. To learn more, visit the deep dive blog post.
  • AWS Lambda durable execution SDK for .NET is now generally available: You can now build resilient, long-running workflows in C# using Lambda durable functions, without implementing custom progress tracking or integrating an external orchestration service. The SDK is a natural fit for multi-step applications like payment processing pipelines, AI agent orchestration, and human-in-the-loop approvals, it checkpoints progress automatically and can pause execution for up to a year. If you’re a .NET developer building serverless workflows, this removes a lot of the plumbing you used to write by hand.
  • Amazon Bedrock AgentCore now delivers unified observability with traces and logs in a single log group: Amazon Bedrock AgentCore now delivers agent traces and prompts to the same Amazon CloudWatch log group as your agent’s logs. Previously, telemetry was split across destinations, trace spans went to a shared log group while prompts, inputs, and outputs went to a separate one, so debugging a single agent invocation meant searching in multiple places. You can now debug an invocation in one place, and apply fine-grained access control and customer-managed key (CMK) encryption at the individual agent level.
  • Amazon Connect delivers more natural agentic voice experiences: Amazon Connect now supports more natural, human-sounding agentic voice experiences across 50+ languages, including Portuguese, Spanish, French, Italian, Japanese, Korean, and Thai, with over 100 new voice options and conversational improvements that make AI interactions sound more fluid. Connect’s agentic self-service lets AI agents understand, reason, and take action across voice and digital channels, adapting to a customer’s tone and sentiment. You can now build contact center experiences that feel natural to callers in far more of the languages your customers actually speak.
  • Amazon SageMaker Unified Studio now supports Amazon OpenSearch: You can now query and analyze your search and log analytics data from Amazon OpenSearch directly alongside other data assets in Amazon SageMaker Unified Studio. With this connection, you can combine operational search data in OpenSearch with data from sources like Amazon Redshift, Amazon S3, and relational databases, all within a single, governed environment. It’s especially useful when you need to correlate analytical and operational workloads, such as joining application logs with transactional data to uncover insights.
  • Amazon CloudWatch announces coding agent insights: Amazon CloudWatch now gives engineering leaders visibility into how AI coding tools are driving value across their organization. Coding agent insights integrates with the Claude apps gateway for AWS to collect telemetry from Claude Code without additional instrumentation, and also supports agents like Codex and GitHub Copilot. As teams scale AI coding adoption, you can now measure the return on that investment with metrics built on OpenTelemetry, no custom instrumentation required.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Other AWS news
Here are some additional posts and resources that you might find interesting:

Upcoming AWS events
Check your calendar and sign up for upcoming AWS events:

  • AWS Summits: AWS Summits are free events that bring the cloud and AI community together to connect, learn, and explore the latest technologies. Browse the full calendar to find a Summit near you in the second half of 2026.
  • AWS Community Days: Community-led conferences where content is planned, sourced, and delivered by community leaders. If you’re in Latin America, don’t miss AWS Community Day Belo Horizonte on August 22, registration is open at awscommunityday.com.br.

Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development. Browse here for upcoming AWS-led in-person and virtual events and developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

Amazon SQS turns 20: Two decades of reliable messaging at scale

13 juillet 2026 à 20:13

On July 13, 2006, we launched Amazon Simple Queue Service (Amazon SQS) as one of the first three services available to customers, alongside Amazon EC2 and Amazon S3. We had learned firsthand that distributed systems need a reliable way to pass messages between components without creating tight dependencies. If one service called another directly and that service was slow or unavailable, failures cascaded through the entire system. Message queuing solved this by letting services communicate asynchronously: a producer could drop a message into a queue and move on, while a consumer picked it up when ready. This approach kept individual service failures from affecting the rest of the system.

When Amazon SQS launched publicly in July 2006, it made this pattern available to every AWS customer. Twenty years later, that core function, decoupling producers from consumers, remains the reason customers use SQS. The scale, performance, and operational controls around it look very different now though.

Jeff Barr covered the first 15 years of SQS milestones in his 15th anniversary post, from the original 8 KB message limit in 2006 through FIFO queues, server-side encryption, and Lambda integration. Over the last five years, we have continued to scale SQS, added stronger security defaults, and introduced new capabilities that address increasingly complex workload patterns.

Key milestones between 2021 and 2026
High throughput mode for FIFO queues (2021): In May 2021, we launched general availability of high throughput mode for FIFO queues, supporting up to 3,000 transactions per second (TPS) per API action, a tenfold increase over the previous limit. We continued raising this ceiling over the following two years: to 6,000 TPS in October 2022, to 9,000 TPS in August 2023, and to 18,000 TPS in October 2023, before reaching 70,000 TPS per API action in select Regions by November 2023.

Server-side encryption with SSE-SQS (2021): In November 2021, we introduced server-side encryption with Amazon SQS-managed encryption keys (SSE-SQS), giving customers an encryption option that required no key management. In October 2022, we made SSE-SQS the default for all newly created queues, so customers no longer needed to explicitly enable it.

Dead-letter queue redrive enhancements (2021): We progressively expanded how customers recover unconsumed messages from dead-letter queues. In December 2021, we added DLQ redrive to source queue directly in the SQS console. In June 2023, we extended this capability to the AWS SDK and CLI through new APIs, including StartMessageMoveTask, CancelMessageMoveTask, and ListMessageMoveTasks. In November 2023, we added redrive support for FIFO queues.

Attribute-based access control, ABAC (2022): In November 2022, we introduced ABAC, giving customers the ability to configure access permissions based on queue tags rather than maintaining static policies as resources scaled.

JSON protocol support (2023): In November 2023, we added support for the JSON protocol in the AWS SDK, reducing end-to-end message processing latency by up to 23% for a 5 KB payload and lowering client-side CPU and memory usage.

Amazon EventBridge Pipes console integration (2023): We added the ability to connect a queue directly to EventBridge Pipes from the SQS console, routing messages to a broad range of AWS service targets without writing custom integration code.

Extended Client Library for Python (2024): We brought the Extended Client Library, previously available for Java, to Python developers, allowing messages up to 2 GB to be sent through SQS by storing the payload in Amazon S3 and passing a reference through the queue.

FIFO in-flight message limit increase (2024): We increased the in-flight message limit for FIFO queues from 20,000 to 120,000 messages, so consumers can process significantly more messages concurrently without being constrained by the previous ceiling.

Fair queues for multi-tenant workloads (2025): We introduced fair queues to mitigate the noisy neighbor problem in multi-tenant standard queues. By including a message group ID when sending messages, customers can prevent a single tenant from delaying message delivery for others, without any changes required on the consumer side.

1 MiB maximum message payload size (2025): We increased the maximum message payload from 256 KiB to 1 MiB for both standard and FIFO queues, helping customers send larger messages without offloading data to external storage. AWS Lambda event source mapping for SQS was updated in parallel to support the new payload size.

The constant underneath the change
Despite two decades of feature additions, the fundamental use case for SQS has not shifted. Customers use it to decouple services, buffer bursts of traffic, and build systems that stay resilient when individual components fail. That same pattern now extends to AI workloads. Customers use SQS queues to buffer requests to large language models, manage inference throughput, and coordinate communication between autonomous AI agents operating as independent services. For an example of this architecture in practice, read Creating asynchronous AI agents with Amazon Bedrock.

To learn more about Amazon SQS, visit the Amazon SQS product page, review the developer guide, or explore recent updates on the AWS Blogs.

— Esra

AWS Weekly Roundup: AWS Builder Center at 1 year, Network Scanning in Security Hub, Loom for AWS, and more (July 13, 2026)

13 juillet 2026 à 18:18

AWS Builder Center turned one year old last week. Launched on July 9, 2025, the platform has grown from a community hub with Wishlist voting, community profiles, and a toolbox into a full ecosystem with sandbox environments, workshops, Spaces, and a Builders’ Library. To mark the anniversary, Rick Suttles published a full feature timeline covering everything shipped over the past year: AWS Capabilities by Region (1,500+ services across 37 Regions), Spaces for community-created groups, workshops with category and complexity filters, badges and streaks, article series, view counts, saved items, student status, availability notifications, sign-in with GitHub and Amazon, and sandbox environments.

Jeff Barr published a retrospective summarizing Builder Center’s first year. Since launch, 5,548 authors have published 6,448 articles with more than 10.4 million page views combined. Builders have earned 99,226 badges since the badge system launched in March 2026. Community members have submitted 565 wishes, 10 of which have shipped with another 20 on the near-term roadmap.

The top community article Building an AWS Study Buddy with MCP + Strands Agents SDK by Dineshraj Dhanapathy reached 50,000+ views. Chris Miller’s Migrating an EOL Linux Server to AWS in 8 Hours with Kiro followed at 45,000+, and Yash Aggarwal’s AIdeas: NeuroVoice – Multimodal AI for Early Screening of Neurological Diseases article reached 38,000+.

The week’s headline addition is Sandbox Environments by Rick Suttles. Sandboxes give you a free, pre-provisioned AWS account to complete a workshop exercise. Each environment is active for 8 hours, after which the account and all its resources are automatically de-provisioned. You can have one active sandbox at a time and request one per week. No personal AWS account, credit card, or manual cleanup required.

Last week’s launches
Here’s what else happened this week.

  • AWS Security Hub introduces Network Scanning – Security Hub introduced Network Scanning, a capability that identifies resources in your environment that are reachable from the public internet. Network Scanning probes your resources from the internet to detect actual reachability, complementing the existing network reachability findings in Security Hub that identify configurations that could make a resource reachable. It discovers public IP addresses, virtual machines, and load balancers across your AWS and Azure environments, identifies reachable ports, and determines what services are running behind them. Each reachable port generates a Security Hub finding with evidence of the port and service discovered. Security Hub Exposures then automatically correlates these findings with other findings and resource configurations to determine broader risk. Existing customers can enable Network Scanning in individual accounts and Regions, or across an organization through a configuration policy. For new customers, Network Scanning is on by default. It is included with Security Hub Essentials at no additional cost.
  • Security Hub also extends unified security management to Microsoft Azure – Security Hub now monitors Microsoft Azure resources, providing unified posture management, vulnerability management, and security response across both clouds. It automatically discovers Azure VMs, container images, Function Apps, and identities, and evaluates them for misconfigurations, internet exposure, and software vulnerabilities. AWS and Azure findings appear in the same prioritized view with the same formats and automation workflows.
  • Amazon SageMaker Studio integrates with Hugging Face for one-click model deployment and customization – You can now go from discovering a model on Hugging Face to working with it in SageMaker Studio in a single click. Select any supported model on Hugging Face and choose “Customize on SageMaker AI” or “Deploy on SageMaker AI” to land directly on the corresponding workflow page with the model pre-loaded. New customers receive a Studio environment created in seconds with pre-configured permissions for serverless model customization (including fine-tuning with custom reward functions for reinforcement learning), model evaluation, and deployment to SageMaker or Bedrock endpoints. Verified customers receive default GPU access to G5, G6, and G4dn instances without requesting quota increases, and quota utilization is visible directly inside the Studio environment.
  • Amazon EKS Auto Mode and Amazon ECS Managed Instances reduce GPU management fees by up to 60% – Beginning July 1, 2026, EKS Auto Mode and ECS Managed Instances reduce management fees for accelerated instance types: G-series fees are down 35%, and P-series and AWS Trainium fees are down 60%. The reductions apply automatically to existing clusters and require no action from customers. Both services include capabilities built for accelerated workloads. EKS Auto Mode provides automatic parallel image pulling on GPU instances with local NVMe storage and accelerator-aware node repair. ECS Managed Instances provides GPU metrics through Amazon CloudWatch Container Insights and automatic health monitoring for GPU hardware failures.
  • Amazon Aurora DSQL change data capture (CDC) is now generally available – Aurora DSQL CDC streams the results of insert, update, and delete operations as change events to Amazon Kinesis Data Streams. You can use it to synchronize data across microservices, trigger Lambda functions, or deliver changes to S3, Redshift, and OpenSearch Service through Amazon Data Firehose. CDC streaming is designed to have zero impact on database workload performance and requires no infrastructure to manage.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Other AWS news
Here are some additional posts you may find useful:

  • Building secure AI agents at scale: Introducing Loom for AWS – Loom is an open-source enterprise platform for building agents with AWS Strands Agents and deploying them on Amazon Bedrock AgentCore Runtime. It provides a unified management UI and backend API with identity provider integration, scope-based authorization, multi-persona navigation, and full lifecycle management for agents, memory, MCP servers, and agent-to-agent integrations. Loom enforces automated resource tagging for cost attribution, implements RBAC and ABAC for multi-tenant security, uses paved-path blueprints for agent deployments, manages identity propagation through delegated actor chains, integrates with AWS Agent Registry for discovery and governance, and supports human-in-the-loop review before sensitive actions. The project is available in AWS Labs on GitHub.
  • Introducing Claude apps gateway for AWS – The Claude apps gateway is a self-hosted control plane that gives organizations centralized control over access, cost, and policy for Claude Code and Claude Desktop. It connects to any OIDC-compliant identity provider, enforces managed settings on every request, routes inference to Amazon Bedrock or Claude Platform on AWS, and supports per-user and per-group spend caps. The gateway runs as a stateless container in your private network, backed by a PostgreSQL database for short-lived sign-in state. No long-lived secrets are stored on developer machines. Deploy it through Amazon Bedrock to keep data within the AWS security boundary, or through Claude Platform on AWS for the native Claude platform experience.
  • Introducing OAuth support for AWS MCP Server – You can now connect agents to the AWS MCP Server using browser-based OAuth with the same credentials you use for the AWS Console or CLI. The new sign-in path supports IAM federation, AWS IAM Identity Center, and root or IAM users. AWS Sign-In issues short-lived access tokens and refresh tokens, with automatic token management so developers stay authenticated across restarts. For headless use cases, a non-interactive flow lets applications with existing AWS credentials obtain OAuth access tokens through the create-oauth2-token-with-iam API. New governance controls include OAuth-specific IAM condition keys, token introspection and revocation, dynamic client registration, and CloudTrail audit elements.

For a full list of AWS blog posts, be sure to keep an eye on the AWS Blogs page.

Upcoming AWS events
Check your calendar and sign up for upcoming AWS events:

Visit the AWS Builder Center to meet other builders, contribute solutions, and find resources that help you keep building.

Wishing everyone a restful and enjoyable summer. Whether you’re building, learning, or recharging, I hope you find time for all three. I’ll be heading to Scandinavia for a few weeks to trade the heat for some cooler weather and longer evenings. Come back next week for more news!

— Esra

Top announcements of the AWS Summit in New York, 2026

17 juin 2026 à 18:36

Today at the AWS Summit in New York City, Swami Sivasubramanian, AWS VP of Agentic AI, provided the day’s keynote.

Here’s our roundup of the biggest announcements from the event:

New in agents customers create
We’re introducing new capabilities on Amazon Bedrock AgentCore: connecting AI agents to organizational, web, and paid knowledge, helping teams find and fix what’s going wrong in production, and enforcing controls that scale as agents grow more capable.

Together, these capabilities help you build more capable agents faster, govern those agents with controls that scale, and improve them continuously. To learn more, read our blog post covering all the new features.

New in agents for securing

New in agents for building

  • Introducing Kiro for iOS – Kiro introduces a native iOS app, available in a gated preview, built for real engineering work that gives developers a new surface to kick off, monitor, steer, and interact with their Kiro sessions directly from their phone. That means you can now start sessions, check back when they’re done, review diffs, and approve changes all while staying connected to your work with no laptop running.
  • AWS DevOps Agent adds release management capabilities to assess code changes before production – You can use a new release readiness review of code changes and autonomous release testing. These new features verify every change against the natural language standards you give to the DevOps Agent and run change-specific tests in production-like environments.
  • Proactively reduce tech debt autonomously with AWS Transform – continuous modernization – You can use continuous analysis (preview) to automatically scan your code repositories against configurable baselines and generates findings in hours, not weeks. Once you’ve identified and prioritized findings, you can configure autonomous remediations that generate pull requests for affected repositories automatically.

New in agents for works

With the launch of Amazon Quick’s new autonomous agents, you can create agents that work in the background with specific expertise, tone, and access to tools. You can create a finance agent to process orders as they come in, or a sales agent monitoring interactions across your CRM, emails, and Slacks to proactively draft follow-ups, flag risks, or recommend next steps.

We are also releasing a new activity feed that is tailored to how you work. It consolidates email, messaging, calendar, and tasks into a single prioritized view, learns which messages you always answer fast, which threads you skip, and what topics drive your week.

To learn more, look the demo of Amazon Quick – AI Assistant.

In addition to the keynote announcements, we have other important launches this week:

  • Amazon S3 annotations: attach rich, queryable context directly to your objects – Amazon S3 now lets you attach up to 1 GB of rich, mutable, and queryable context directly to your objects using annotations, purpose-built for AI agents and autonomous workflows that need to discover, understand, and act on data at scale without maintaining separate metadata systems.
  • Amazon ECS announces faster service auto scaling – Amazon ECS service auto scaling now detects and responds to load changes faster with support for high resolution (20-second) metrics and metric publishing optimizations. In AWS benchmarking tests, time to trigger scale-out improved from 363 seconds to 86 seconds (76% faster, 4.2x), and total time to scale and provision new tasks improved from 386 seconds to 109 seconds (72% faster, 3.5x).
  • Amazon EC2 G7 instances accelerated by NVIDIA RTX PRO 4500 Blackwell Server Edition GPUs – AWS is the first major cloud provider to support NVIDIA RTX PRO 4500 Blackwell Server Edition GPUs. G7 instances are accelerated by these GPUs with custom sixth-generation Intel Xeon Scalable processors, delivering up to 4.6x AI inference performance and up to 2.1x graphics performance compared to G6 instances.
  • Strands Agents introduces new capabilities – Strands is an open source toolkit for building production agents. You can use now better context management in the Harness SDK, a new isolated execution environment with Strands Shell, and chaos testing and red teaming in Strands Evals.

Updated on June 18, 2026 — Added new important launches on June 18.

Introducing Amazon Bedrock Managed Knowledge Base for faster, more accurate enterprise AI applications

17 juin 2026 à 17:09

Today, we’re announcing Amazon Bedrock Managed Knowledge Base, a new set of capabilities that enables developers to build enterprise-grade generative AI applications with their proprietary data in minutes. Organizations building agentic AI applications need secure, reliable, and up-to-date access to enterprise-wide data to deliver accurate, fast, and trusted outcomes. Managed Knowledge Base abstracts away the complexity of building and managing retrieval-augmented generation (RAG) pipelines, allowing developers to focus on business outcomes rather than infrastructure management.

Developers building knowledge bases for their agents face three key challenges today:

  • Connecting to enterprise data: Enterprise knowledge lives across disparate systems with different content types, access control lists, and document formats. Building and maintaining custom connectors for each source adds complexity that slows down development.
  • Optimizing RAG accuracy: Best practices for retrieval-augmented generation keep evolving. Developers need to experiment with different parsing strategies, chunking approaches, embedding models, and agentic retrieval behaviors to get accurate answers from their data.
  • Managing infrastructure at scale: Organizations need to serve large knowledge bases with millions of documents, or manage thousands of smaller knowledge bases across teams. Both patterns require reliable infrastructure, security enforcement, and cost control.

These challenges require developers to repeatedly perform undifferentiated work instead of focusing on their applications.

Amazon Bedrock Managed Knowledge Base addresses these challenges by abstracting away the multiple infrastructure components developers traditionally have to assemble and maintain themselves (storage, retrieval, embeddings, re-ranking, and foundation model selection) into a single managed primitive. By default, the service automatically selects and manages a default embeddings model, re-ranker model, and foundational model on your behalf, so you can get up to speed quickly without needing to pick or maintain one yourself. On top of this managed foundation, three core innovations further improve ease of use and accuracy:

  • Native data connectors: Six pre-built ingestion connectors that natively pull enterprise data and permissions from SaaS applications, eliminating the overhead developers face in managing application-specific requirements. At launch, we support Amazon S3, SharePoint, Confluence, Web Crawler, Google Drive, and OneDrive.
  • Smart Parsing: Different content types and sources require different approaches to achieve accurate retrieval. Smart Parsing handles this complexity automatically, selecting the right parsing strategy for each data type and connector to provide the highest accuracy for your agents.
  • Agentic Retriever: Optimized for complex queries that require multiturn, multihop retrieval within a single knowledge base or across multiple knowledge bases. Agentic Retriever automatically infers end-user intent and draws relevant context from institutional knowledge spread across data sources and modalities.

With just a few lines of code, Amazon Bedrock Managed Knowledge Base automatically manages and scales the end-to-end RAG pipeline that powers your enterprise knowledge agents. For agent builders, it’s available as a pre-built target type in Amazon Bedrock AgentCore Gateway, reducing integration to a few lines of code, auto-generating role-based permissions, and providing observability and evaluation metrics in the AgentCore Observability dashboard.

Getting started with Amazon Bedrock Managed Knowledge Base
Creating a Managed Knowledge Base is straightforward. Navigate to the Amazon Bedrock AgentCore console or the Amazon Bedrock console, open the Knowledge Bases page, and choose Create Managed KB. The experience is the same in both consoles.

Picture 1 – Knowledge Bases list page in the Amazon Bedrock AgentCore console showing the Type column with different KB types and the Create Managed KB button

When creating a new Knowledge Bases, you can connect to your enterprise data sources by choosing from the list of supported connectors directly from a dropdown. AWS Identity and Access Management (IAM) roles are automatically created, and you can choose to edit these permissions if needed:

Picture 2 – Create Knowledge Base page showing the Data source dropdown expanded with all supported connectors: Amazon S3, Confluence, Custom, Google Drive, One Drive, SharePoint, and Web Crawler

An optimized set of defaults will be presented, allowing you to create your knowledge base in just a few clicks. Once the data is synced, you can integrate the knowledge base with your agent or provide it as a tool for your foundation model and start querying.

Smart Parsing for accurate data ingestion
One of the key challenges in building knowledge bases is preparing diverse data types for accurate retrieval. Once you point Managed Knowledge Base at your data sources, Smart Parsing automatically determines the optimal parsing strategy for each data type and connector, no extra configuration is required.

Smart Parsing combines multiple techniques:

  • Connector-specific data models: Optimized handling for each data source. For example, the Web Crawler connector preserves HTML structure including embedded images and tables, ensuring rich content is not dropped during ingestion. SharePoint connectors maintain document hierarchy and relationships between files.
  • Multimodal processing: Automatic detection and processing of different content types within documents. The system identifies bounding boxes in documents, then sends them to foundation models for data extraction, captioning, and scene description in video files.
  • Optimized chunking: Smart Parsing leverages foundation models to understand document structure and extract meaningful content, ensuring that complex documents with mixed formats are properly indexed. Intelligent defaults balance retrieval accuracy with performance based on document type and content structure, while advanced users can customize chunking strategies when needed.

This automated approach eliminates weeks of experimentation typically required to achieve production-quality retrieval accuracy, while still preserving the flexibility to customize when needed.

Using Agentic Retriever for complex queries
After your data is ingested, you can start querying your knowledge base. Generative AI applications often struggle with complex user queries that require reasoning, recursive multi-step retrieval, and intermediate evaluations of results. Consider a user asking two related questions: “What is the cloud infrastructure budget for the ML platform team?” and “Does our expense policy allow prepaying annual commitments?” A single retrieval step might surface documents about the ML platform team but fail to connect the budget information with the expense policy needed to fully answer the question.

Picture 3 – Agentic Retriever decomposes complex user queries into a step-by-step plan, performing multi-hop retrieval across multiple knowledge bases and combining results to deliver accurate, grounded responses

Agentic Retriever solves this by creating a step-by-step query plan: 1. Which team owns the ML platform, and what is their cloud infrastructure budget? 2. What does the expense policy say about prepaying annual commitments? 3. Does the policy allow the ML platform team to prepay against this budget?

The system performs multi-hop retrieval and reasoning at each step, and once it has gathered sufficient relevant passages, it stops the search process and returns the top results. By abstracting away the complexity of building a separate multi-hop reasoning pipeline, this approach dramatically improves accuracy for complex queries while letting developers focus on their agentic search applications instead of orchestration logic.

You can try Agentic Retriever directly from the test panel of your knowledge base in the Amazon Bedrock AgentCore console. Select Agentic retrieval only as the retrieval type to let the system automatically plan and execute multi-step queries across your knowledge bases:

Picture 4 – Test Knowledge Base panel showing Agentic retrieval with answer generation selected as the retrieval type, with model selection and maximum agentic iterations options

Enabling MCP with Bedrock AgentCore
Amazon Bedrock Managed Knowledge Base seamlessly integrates with AgentCore Gateway as a native target type. This integration eliminates the need for manual integration and provides built-in observability, policy enforcement, and automatic permission management.

You can navigate to the Amazon Bedrock AgentCore console or SDK and create an AgentCore Gateway or select an existing one. When adding targets to your gateway, you will find Knowledge Base as a new pre-built target type alongside other options such as MCP server, Lambda ARN, REST API, and other integrations. Simply select your knowledge base ID to expose it through the gateway:

Picture 5 – Add targets page in AgentCore Gateway showing Knowledge Base as a new pre-built target type, with the knowledge base ID selector and runtime retrieval mode options

Add targets page in AgentCore Gateway showing Knowledge Base as a new pre-built target type, with the knowledge base ID selector and runtime retrieval mode options

Gateway exposes the standard Model Context Protocol (MCP), so the knowledge base tools are automatically discovered by clients from any MCP-compatible framework, including Strands Agents, LangChain, CrewAI, LlamaIndex, and LangGraph. No custom integration code is required.

Model choice and flexibility
Amazon Bedrock Managed Knowledge Base preserves the flexibility developers expect from Amazon Bedrock. Every foundation model available on Bedrock can power the generation step, and developers can select from different embedding and re-ranking models to optimize retrieval for their specific use case, enabling teams to fine-tune accuracy and cost-performance without changing infrastructure.

Unlike managed solutions that lock you into specific model providers, Amazon Bedrock Managed Knowledge Base separates the infrastructure management (connectors, parsing, storage, retrieval orchestration) from model selection. This means you can:

  • Take advantage of the latest models: Adopt the latest embedding, re-ranking, and foundation models as they become available to improve accuracy, latency, and cost for your application without rebuilding your RAG pipeline.
  • Optimize for price-performance: Choose smaller, faster models for simple queries and more capable models for complex reasoning tasks, all using the same knowledge base infrastructure.
  • Use Bedrock embedding models: While Smart Parsing provides optimized defaults, you can configure Bedrock embedding models when your domain requires specialized semantic understanding.
  • Maintain consistency with existing applications: If you’re already using Bedrock Knowledge Bases APIs (Retrieve, StartIngest, StopIngest, IngestKnowledgeBaseDocuments), Managed Knowledge Base uses the same APIs, so migration requires no code changes, just point to the new knowledge base ID.

This approach ensures you can spend time on your generative AI application without losing the ability to change models based on evolving requirements or new model capabilities.

Get started today
Amazon Bedrock Managed Knowledge Base is available today in the US East (N. Virginia), US West (Oregon), Asia Pacific (Sydney, Tokyo), Europe (Dublin, Frankfurt, London), and AWS GovCloud (US-West) Regions. For Regional availability and future roadmap, visit AWS Capabilities by Region.

With Bedrock Managed Knowledge Base, you pay for what you use with no upfront commitments. Pricing is based on two dimensions: the size of indexed data stored and the number of retrievals performed (on-demand). For detailed pricing information, visit the Amazon Bedrock pricing page. Bedrock is also a part of the AWS Free Tier that new AWS customers can use to get started at no cost and explore key AWS services.

These capabilities work with any open source framework such as CrewAI, LangGraph, LlamaIndex, and Strands Agents, and with any foundation model. Bedrock services can be used together or independently, and you can get started using your favorite AI-assisted development environment with the AgentCore open source MCP server.

To learn more and get started quickly, visit the Bedrock Knowledge Bases Developer Guide.

Daniel Abib

 Updated on June 19, 2026 — Fixed correct screenshots to create a new Managed KB.

AWS DevOps Agent adds release management capabilities to assess code changes before production (preview)

17 juin 2026 à 16:57

Today, we’re announcing a new release management capability in AWS DevOps Agent that is now available in preview. AWS DevOps Agent is your always-available teammate that spans software changes and operations across AWS, multicloud, and on-premises environments. The practice of DevOps aims to make software change and operations smooth and increasingly autonomous, and AWS DevOps Agent delivers on both by leveraging its deep understanding of your environment, your services, their dependencies, and how they behave in production. Already generally available for post-deployment operations, it autonomously investigates incidents, provides root cause analysis and mitigation steps, and delivers targeted recommendations to prevent recurring issues. With today’s preview, AWS DevOps Agent adds release readiness review of code changes and autonomous release testing. These new features verify every change against the natural language standards you give to the DevOps Agent and run change-specific tests in production-like environments. AWS DevOps Agent now supports teams from code creation to production, helping reviewers and testers keep pace with the volume of AI-generated code.

As development teams adopt AI coding tools, the volume of pull requests moving through delivery pipelines has increased faster than review and testing processes can handle. When teams are under pressure to keep up, reviews are approved without thorough examination, and test environments drift from production. The value that coding agents generate sits waiting in review queues instead of reaching end users. At the same time, AI models are increasingly capable of catching functional and security issues that human reviewers might miss under time pressure, making speedy and safe delivery a requirement rather than a tradeoff.

The release readiness review feature evaluates every code change against production requirements, dependency safety, and the standards and best practices you provide to the DevOps Agent. The agent checks cross-repository dependency risks that could affect other services, access control changes against AWS Well-Architected Framework best practices, and compliance with any standards you have defined. When no standards are provided, the agent applies general best practices. As part of the review, the agent also runs your software in an AWS-managed isolated environment, executing lightweight user journey tests to verify the software builds, runs, and passes basic functional checks before the change enters the pipeline. Findings appear in the AWS DevOps Agent console and as comments on pull requests in GitHub or GitLab. You can also invoke reviews directly from your IDE through the Kiro power or Claude Code plugin, so developers can identify and fix dependency risks, standards violations, and access control issues before the change is committed to version control.

The autonomous release testing feature goes further, generating and running change-specific test plans for web and API-based applications in customer-provisioned, production-like environments before the change merges. Rather than running a static test suite, the agent reasons about what the change does and constructs tests tailored to it, covering functional correctness, behavioral regressions, and integration scenarios that a manually maintained test plan might not anticipate. Every test run produces structured artifacts including metrics, logs, traces, and an execution summary, giving reviewers a consistent record of what was tested and what the results were.

Getting started with AWS DevOps Agent release management
This walkthrough shows how to run an on-demand release readiness review using the AWS DevOps Agent web app. Before you begin, confirm that you have at least one GitHub or GitLab repository connected to your Agent Space. Once your repositories are connected, AWS DevOps Agent will index your code and build a knowledge graph of cross-repository and cloud dependencies.

To open the web app, navigate to the AWS DevOps Agent console, select your Agent Space, and choose the Web app tab. Choose Operator access to open the web app.

Without standards configured, the agent applies general best practices. To tailor reviews to your internal standards, navigate to Knowledge, then choose the Instructions tab. You will see a list of instruction sets, each scoped to a specific agent or task. Choose View next to Release readiness review to edit the instructions for production-readiness change review. Write your internal standards in plain English. For example, you can define infrastructure and data standards on encryption or network access rules, best practices that warn without blocking such as logging and observability requirements, and sensitive data classification best practices that identify applications or resources requiring higher security measures. To apply instructions across all agents in your space, choose View next to All agents.

You can trigger a release readiness review in two ways: by submitting a pull request to a connected repository, or by entering an on-demand query in the chat interface. To run an on-demand review from chat, choose New chat and enter a request such as:

Perform a production risk analysis on my repository branch

The agent will ask for the repository and branch you want to analyze. You can provide a branch name, a pull request number, or a commit SHA. Once you confirm your selection, the agent queues the review and analyzes the change for production risks, including infrastructure impacts, configuration changes, and potential issues.

After the review completes, you can ask follow-up questions directly in the chat to explore the findings in more detail. For example, you can ask which downstream consumers a change affects, and the agent will return a structured breakdown of in-repository and cross-repository consumers that will break, the specific files and line numbers affected, and the recommended steps to resolve the issue before deployment.

After submitting a review request, navigate to Changes in the left navigation pane. The Proposed changes table shows each review that has run, including the proposed change description, its source, category, status, and when it was created. You can filter by category or status to find specific reviews, or search by name using the search bar. Choose any entry to open the full execution detail.

The Timeline tab shows the agent’s step-by-step reasoning process, including the tools it called, the dependencies it consulted, and the observations it made at each step. Each entry is timestamped, giving you a complete record of how the agent built its understanding of the change and reached its conclusion.

Choose the Report tab to see the final recommendation. The report opens with a summary header showing the recommended action, the number of critical issues found, the commit revision, and the number of files changed. The recommended action is either BLOCK, Proceed with Caution, or Safe to Release.

Below the summary header, the Analysis section explains why the recommendation was made, citing specific risks and the evidence the agent found to support its conclusion. The Issues section lists each finding by severity, giving you a prioritized view of what needs to be addressed before the change can proceed. The Recommendations section provides specific, actionable steps the developer can take to resolve each issue. Finally, the Changes section lists each file that was modified, with the type of change, the category it falls under, and a description of what was changed, so reviewers have a complete picture of what the change does before it merges.

You can also invoke the autonomous release testing feature directly from the chat interface. To run an autonomous release test on a web or API-based application, choose New chat and enter a query such as:

Run a release test on my application deployed at [application URL]

The agent generates a change-specific test plan and executes it in your provisioned environment. Results appear in Changes, where you can review the execution steps and a structured summary of what was tested.

Get started today
The release readiness review and autonomous release testing features for AWS DevOps Agent are available in preview. These features are available at no additional cost during preview in the US East (N. Virginia) Region. For pricing information on other AWS DevOps Agent features, visit the AWS DevOps Agent pricing page.

For configuration details, visit the AWS DevOps Agent user guide.

— Esra

AWS WAF adds AI traffic monetization capability to help content owners charge AI bots for content access

15 juin 2026 à 22:42

AWS WAF now includes AI traffic monetization capability that gives digital content owners and publishers a way to charge AI bots and agents for access to protected web content directly at the network edge. The capability helps content owners and publishers set per-request pricing by content path, bot category, or verification tier without modifying their origin infrastructure or writing application code. Content owners can define granular access policies per agent type, collect payments in stablecoins to their preferred wallet, and monitor revenue and bot activity from a single dashboard.

AI bot traffic now accounts for more than 50% of web traffic for many content providers, with AI-specific crawlers growing more than 300% year-over-year. Unlike traditional search engine crawlers, which index content and return measurable referral traffic back to publisher websites, AI bots consume the same content to generate summaries and responses in AI interfaces, with little to no traffic sent back to the original source. Publishers bear the infrastructure costs of serving that traffic without the page views, ad impressions, or subscription conversions that typically offset those costs. AWS WAF Bot Control already gives customers visibility into bot activity and the ability to block or rate-limit traffic, but setting pricing and collecting payment from AI agents has not been possible until now. AI traffic monetization is a new Bot Control capability that closes that gap, giving content owners and publishers a way to configure pricing rules directly through the AWS WAF console and collect payments from AI agents through third-party payment integrations, without building custom payment infrastructure or negotiating individual licensing agreements. Payment settlement and verification flows are provided by Coinbase’s x402 Facilitator. Integration with Stripe for direct account payments and Machine Payments Protocol (MPP) support is coming soon.

Getting Started with AI Traffic Monetization
Before configuring monetization, confirm that AWS WAF Bot Control is enabled at Common or Targeted level on the web ACL associated with your CloudFront distribution. Bot Control provides the agent classification that monetization rules depend on. If you have not set this up yet, visit Adding the AWS WAF Bot Control managed rule group to your web ACL documentation. In the AWS Management Console, go to WAF & Shield and choose Protection packs (web ACLs) in the left navigation pane to get started.

A protection pack is the core configuration unit for AI traffic monetization. It defines which content paths are monetized, what each agent verification tier is charged, which payment methods you accept, and what license terms apply. To create one, choose Create protection pack (web ACL).

In Tell us about your app, select one or more app categories that describe your content (for example, Content & publishing systems, E-commerce & transaction platforms, or Enterprise & business applications), and choose an App focus. AWS WAF uses these selections to recommend suitable security protections for your configuration.

In Select resources to protect, choose Add resources to associate regional or global resources such as CloudFront distributions with this protection pack. You can skip this step and add resources later.

In Choose initial protections, select from AWS WAF managed rule packages based on your app category and resource selections. You can also choose individual rules instead of packages.

In Name and describe, provide a name and optional description for the protection pack.

Optionally, expand Customize protection pack (web ACL) to configure additional settings including pricing tiers, payment methods, content scope, and license terms.

When finished, choose Create protection pack (web ACL).

Once your protection pack is in place, review the AI traffic analysis dashboard to understand the impact of AI bot traffic on your content before setting your pricing strategy. In the WAF & Shield console, go to AI traffic analysis in the left navigation pane. Select your protection pack (web ACL) from the dropdown to populate the dashboard.

The AI traffic analysis dashboard breaks down traffic into four categories visible in the bot traffic overview panel: All bot requests, AI bot requests, Verified AI bot traffic, and Unverified AI bot traffic. The dashboard surfaces infrastructure impact metrics including bandwidth consumed, estimated monthly cost, and peak request rates. A per-path heatmap shows which content paths receive the most AI bot activity by hour, giving you the data you need to make informed pricing decisions.

AWS WAF Bot Control classifies over 650 distinct AI bot and agent types including GPTBot, Claude-Web, and Perplexity-Bot, and assigns each a verification tier:

  • Verified: Agent identity confirmed through Web Bot Auth (WBA) Ed25519 cryptographic signature, or sourced from a documented IP range with a known set of user-agents and domain names.
  • Unverified: Agent recognized through user-agent matching, behavioral fingerprinting, and IP reputation, but identity not cryptographically confirmed.

Once you have reviewed your traffic patterns, return to Protection packs (web ACLs), select your protection pack from the list, and choose Configure AI monetization from the right panel to set pricing and access policies. Each protection pack defines the pricing, agent policies, accepted payment methods, and license terms that apply to a defined set of content paths. You can create multiple protection packs and apply different pricing to different content zones within the same distribution. Once created, associate the protection pack with your web ACL by opening the web ACL and choosing Add protection pack.

For each agent verification tier within the pack, you can assign one of six actions: Monetize (return a 402 with pricing), Allow (grant free access), Block (deny access entirely), Count (log without charging), CAPTCHA (present a puzzle to verify a human sender), or Challenge (run a silent check to verify the client is a browser, not a bot).

In the Edit monetization configuration page, configure the following:

Under Payment settlement, select one or more blockchain networks for stablecoin payments. Any wallet address on the supported networks is accepted, whether self-managed or hosted by a wallet provider such as Coinbase. For each network, provide your wallet address and set a Base price per page in USDC. You can add multiple networks using Add network. AWS does not process payments or take a fee on content revenue; disbursement is self-managed or managed by your wallet provider.

When a Monetize rule matches an incoming request, AWS WAF returns an HTTP 402 Payment Required response. The response body contains a machine-readable price manifest in JSON format using the x402 open protocol for machine-to-machine payments. The manifest includes the content price in USDC, accepted blockchain networks such as Base and Solana, the destination wallet address, the maximum payment timeout, and the payment scheme.

Any x402-compatible agent runtime can complete this flow autonomously. The client submits a signed payment authorization on their payment network of choice. AWS WAF verifies it, fetches the content, integrates with third-party facilitator services for settling the payment on-chain, and serves the response.

Note that the Monetize action is supported exclusively for web ACLs associated with Amazon CloudFront distributions. Adding a Monetize rule to a regional web ACL is not supported.

Since the Currency mode toggle is available directly in the monetization configuration page, you can switch between Real and Test mode at any time. Before going live, use test mode on non-production traffic to validate pricing, wallet configuration, and x402 payment flows. Note that test mode still enforces x402 payments, but those payments can be made on testnets such as Base Sepolia or Solana Devnet using test funds obtained from faucets such as faucet.circle.com. To activate test mode, toggle Currency mode to Test in your protection pack configuration. AWS WAF returns real price manifests and runs the full payment flow identically to production on the configured test chain. All events are logged with CurrencyMode: TEST. When satisfied with the configuration, toggle Currency mode back to Real to begin processing real payments.

Once you have switched Currency mode to Real, navigate to AI access monetization in the left navigation pane to track monetization outcomes in real time. Note that the AI access monetization dashboard only reflects activity from real currency mode and does not display test transactions.

The Revenue dashboard shows Total revenue, revenue broken down by Verified bots and Unverified bots, and Avg. per request. The Top revenue sources panel groups earnings by bot category, and the AI access patterns panel ranks content paths by revenue generated. Use the Settlements tab to reconcile payments by provider and review payment method distribution and failed payment attempts.

Now Available
AI traffic monetization is available now for Amazon CloudFront customers at no additional charge beyond standard AWS WAF pricing. The capability is available in all edge locations where AWS WAF web ACLs are associated with Amazon CloudFront distributions.

To learn more about AI traffic monetization, see the AWS WAF Developer Guide.

— Esra

AWS Weekly Roundup: AWS FinOps Agent in preview, Gemma 4 on Bedrock, Kiro Pro Max, and more (June 15, 2026)

15 juin 2026 à 13:41

This week, New York City is hosting AWS Summit, bringing together builders, customers, and AWS teams for a full day of announcements, demos, and technical sessions at the Javits Center. I wrote blog posts for some of the Summit launches, so I am excited to see them go live this week. I just won’t be watching from the Javits Center. I’ll be at a four-day music festival, following the launches on my phone while trying to figure out how to put up a tent. If you weren’t able to attend in person like me, the keynote livestream is available on June 17, with Dr. Swami Sivasubramanian, VP of Agentic AI, and Chet Kapoor, VP of Security Services and Observability, covering new capabilities across developer tools, AI infrastructure, and security.

Here’s what happened this week.

Headlines
How frontier teams are reinventing AI-native development – Swami published a detailed post this week drawing on data from experiments across hundreds of Amazon engineering teams. The findings are worth reading carefully if you are thinking about how to structure AI adoption on your own team.

A six-engineer team rebuilt the Amazon Bedrock inference engine in 76 days, a project originally scoped for 30 developers over 12 to 18 months. The median productivity gain across structured pilots with Amazon Stores teams was 4.5x in normalized deployment velocity, with some teams exceeding 10x. Perfect Order Experience went from a two-week feature cycle to shipping in an afternoon. WW Grocery cut design document creation from five days to a few hours.

The post distills these results into five practices for becoming a frontier team. First, invest in agent context: build steering files, coding standards, and structured repositories before writing production code. Second, expect an initial slowdown while workflows are restructured, and push through it. Third, maintain a steady backlog of well-scoped tasks so agents can run in parallel without constant supervision. Fourth, make intent explicit through structured specifications before code generation begins. Fifth, shift testing left so agents can self-correct before code reaches the pipeline.

The post closes with a note that commit velocity is only part of the picture, and that a follow-up will cover release management, operations, security operations, and EOL upgrades.

AWS FinOps Agent is now available in preview – AWS FinOps Agent is a new agent for FinOps practitioners and engineering teams that answers cost questions, surfaces optimization opportunities, investigates cost anomalies, and runs recurring FinOps workflows on a defined schedule. You can use it to query your AWS costs, generate cost reports for finance and engineering teams, and surface rightsizing, idle resource, and Savings Plans recommendations from AWS Cost Optimization Hub and AWS Compute Optimizer. The agent can open Jira tickets on your behalf based on those recommendations. When a cost anomaly is detected, FinOps Agent can automatically investigate the root cause and post findings to a Slack channel.

Last week’s launches
I’ll start with one I wrote this week, then cover the other launches that caught my attention:

  • Amazon EC2 M9g and M9gd instances are now generally available – Powered by AWS Graviton5 processors and built on the sixth-generation AWS Nitro System, M9g instances deliver up to 25% better compute performance compared to Graviton4-based instances, with up to 35% faster performance for web applications, up to 35% for machine learning inference, and up to 30% for databases. Graviton5 is the first processor in the AWS fleet to support PCIe Gen6 and DDR5-8800 memory, and includes a 5x larger L3 cache compared to the previous generation. M9g and M9gd instances offer up to 15% higher network bandwidth and 20% higher Amazon EBS bandwidth on average across sizes compared to M8g. This release also introduces the Nitro Isolation Engine, an enhancement to the Nitro System that uses formal verification to provide mathematically proven isolation between virtual machines — establishing Nitro as the first formally verified cloud hypervisor. M9gd instances add up to 11.4 TB of NVMe SSD local storage with 30% higher IOPS compared to M8gd. Both instance types support Instance Bandwidth Configuration (IBC) for adjusting bandwidth allocation between EBS and VPC networking by up to 25%.
  • Anthropic Claude Fable 5 on Amazon Bedrock – Claude Fable 5 launched on Amazon Bedrock on June 9, bringing extended asynchronous task execution, advanced vision capabilities across diagrams, charts, and PDFs, and proactive self-verification. Access requires opting into data sharing via the Data Retention API before invoking the model; Anthropic requires 30-day retention of inputs and outputs for Mythos-class models. Important note on availability: On June 12, Anthropic asked AWS to revoke access to Claude Fable 5 and Claude Mythos 5 for all users to support compliance with a US Government export control directive. All other models, including Opus 4.8, are unaffected. Read the Anthropic statement for details. AWS will share further updates as they become available.
  • Gemma 4 models are now available on Amazon Bedrock – The Gemma 4 family from Google DeepMind is now available on Amazon Bedrock across three variants: Gemma 4 31B (dense, 256K-token context window, suited for reasoning and coding workloads), Gemma 4 26B-A4B (mixture-of-experts architecture, targeting cost- and latency-sensitive workloads), and Gemma 4 E2B (smallest variant, designed for low-latency interactive use cases). All three support native function calling, structured output, reasoning, response streaming, multimodal input across text, image, video, and audio, and more than 35 languages.
  • Amazon OpenSearch Service launches MCP Apps for agentic observability – Amazon OpenSearch Service now supports MCP Apps, enabling observability workflows inside compatible agentic IDEs including Claude Desktop and VS Code. An AI agent in your local environment can investigate incidents using logs, traces, metrics, and alerts stored in OpenSearch domains, collections, and Amazon Managed Service for Prometheus. Each MCP App tool call returns a dual response: a text summary for the agent to reason over and an interactive visualization rendered in the same conversation thread. Available MCP App tools cover log, metrics, and trace investigation; service performance; topology; dynamic visualizations; agent health; cluster health; and instrumentation scoring.

Other AWS news
Here are some additional posts and updates you may find useful:

  • AWS CLI v1 enters maintenance mode – When CLI v1 enters maintenance mode, the botocore and s3transfer dependencies will be vendored directly into the CLI v1 codebase rather than installed as separate packages. This means upgrading CLI v1 will no longer update the standalone botocore or s3transfer packages, and installing those packages independently will have no effect on the versions used by CLI v1. Environments with both CLI v1 and boto3 installed will contain separate copies of these libraries. New CLI v1 releases will be limited to critical bug fixes and security issues. The recommended path is to migrate to AWS CLI v2.
  • AWS Workload Credentials Provider is now available – AWS Workload Credentials Provider is a lightweight client-side provider that automates deployment of exported certificates from AWS Certificate Manager (ACM) and local caching of secrets from AWS Secrets Manager across AWS and non-AWS workloads. Previously, customers had to build custom EventBridge automation to detect certificate renewals and deploy updates, which becomes harder to maintain as public certificate lifetimes decrease per the CA/Browser Forum mandate. The provider handles this automatically, runs on Windows and Linux, and supports Apache and NGINX. For secrets, it maintains full backwards compatibility with the AWS Secrets Manager Agent.
  • Kiro Pro Max is now available – Kiro has introduced a new Pro Max tier, adding higher usage limits, access to the latest frontier models, and additional agentic capabilities for development teams. Kiro Pro Max is designed for professional developers who need sustained, high-volume use across coding, specification generation, and agent-driven tasks.

Upcoming AWS events
Check your calendar and sign up for upcoming AWS events:

Visit the AWS Builder Center to meet other builders, contribute solutions, and find resources that help you keep building. You can also browse upcoming AWS-led in-person and virtual events, plus developer-focused sessions.

— Esra

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

Now available: Amazon EC2 M9g and M9gd instances powered by new AWS Graviton5 processors

10 juin 2026 à 17:04

AWS Graviton processors have improved steadily across generations, with each iteration delivering advances in compute performance, price-performance, and energy efficiency. At re:Invent 2025, we announced Amazon EC2 M9g, the first Graviton5-powered instances, in preview. Since then, customers have tested M9g across a wide range of workloads and shared their results. ClickHouse saw a 36% performance boost compared to M8g, with zero code changes. Honeycomb achieved 36% better throughput per core compared to Graviton4, across a 6-month A/B test of production observability workloads. HubSpot deployed M9g for MySQL databases and saw query duration drop by up to 60%.

Today, M9g instances are generally available, alongside the new M9gd instances for customers who need high-speed, low-latency local NVMe SSD storage. Both are powered by Graviton5, the most powerful and most energy efficient processor AWS has ever built.

While many Arm-based instances have been introduced across the industry, no one comes close to the breadth and depth of the AWS Graviton footprint. After five generations of custom silicon and eight years of continuous investment, Graviton powers over 350 instance types serving more than 120,000 customers, from startups to large enterprises, a robust ISV partner ecosystem, and a broad set of managed services.

You can use Graviton for a broad variety of workloads, including web applications, microservices, analytics, databases, machine learning (ML) inference, electronic design automation (EDA), gaming, and video encoding. As workloads grow more compute-intensive and data-driven, many have asked for more processing power, along with greater network and storage bandwidth to move more data and complete workloads faster. We’ve also designed these instances to efficiently package compute, memory, and I/O to maximize energy utilization.

As AI shifts from answering questions to taking actions, running code, using tools, evaluating results, and orchestrating multi-step tasks, the demand for CPU compute is growing rapidly. Graviton5 is built for this shift. With 192 cores, a 5x larger L3 cache, up to 33% lower inter-core latency, and DDR5 memory delivering high bandwidth, Graviton5 helps agents spend less time waiting on CPU-bound steps, processing more instructions, handling large numbers of concurrent environments, and keeping accelerators moving.

Meta is deploying Graviton at scale starting with tens of millions of cores to support its agentic AI efforts, making Meta one of the largest Graviton customers in the world. Agentic AI workloads, including real-time reasoning, code generation, and the orchestration of multi-step tasks, are CPU-intensive and benefit from the higher compute performance, larger caches, higher memory bandwidth, and core density in Graviton5.

What’s new in M9g and M9gd
Built on the sixth-generation AWS Nitro System, M9g instances are powered by AWS Graviton5 processors that deliver higher compute performance, larger caches, and improved memory and I/O scalability compared to Graviton4 processors. Graviton5 offers up to 25% better compute performance compared to Graviton4-based instances, with up to 35% faster performance for web applications, up to 35% for machine learning inference, and up to 30% for databases. As the first CPU in the AWS fleet to support the latest generation of PCIe Gen6 and DDR5-8800 memory, AWS Graviton5 instances deliver the fastest memory of any processor instances in the cloud, and 5 times more L3 cache compared to the previous generation. These improvements also come with better energy efficiency, helping you meet sustainability targets without compromising capability.

Networking and storage bandwidth have been expanded to keep pace with compute growth. M9g and M9gd instances offer up to 15% higher network bandwidth and 20% higher Amazon Elastic Block Store (Amazon EBS) bandwidth on average across sizes, with up to twice the network bandwidth for the largest instance size. M9g and M9gd instances also support Instance Bandwidth Configuration (IBC), a feature that helps you adjust the allocation of bandwidth between Amazon EBS and Amazon Virtual Private Cloud (Amazon VPC) networking for an Amazon EC2 instance by up to 25%. IBC can help optimize performance for workloads with specific bandwidth requirements, such as database read and write performance, query processing, and logging. These enhancements support faster data movement and improved throughput for workloads that rely on high I/O performance.

Security and isolation are foundational requirements for running workloads in the cloud. Within the Nitro System, the AWS Nitro Hypervisor is designed to isolate instances from each other as well as AWS operators. With M9g and M9gd instances we are raising the bar on security even further with the introduction of Nitro Isolation Engine. Nitro Isolation Engine is an enhancement to the Nitro System, which enforces isolation of instances and harnesses formal verification to provide assurances of isolation with mathematical precision. Nitro Isolation Engine is a purpose-built component that is responsible for enforcing isolation between virtual machines, including mediation of all access to virtual machine memory, CPU register state, and I/O devices through a minimal set of APIs. Nitro Isolation Engine leverages formal verification, a technique to mathematically demonstrate that the hardware or software behaves as intended, and not just in specific test cases. This intensive verification technique establishes Nitro as the first formally verified cloud hypervisor, pioneering a new standard for mathematically proven cloud security. To learn more about the Nitro Isolation Engine, visit the blog post here. For details on the formal verification results, including scope and assumptions, see our technical white paper.

M9g instances provide one vCPU for every four GiB of memory and are well suited for a broad range of general-purpose workloads, including application servers, microservices, midsize data stores, gaming servers, caching fleets, containerized applications, large-scale Java applications, code repositories, web applications, and agentic AI.

For workloads that need high-speed, low-latency local storage, M9gd instances provide up to 11.4 TB of NVMe SSD storage and 30% higher IOPS and storage performance compared to Graviton4-based M8gd instances. M9gd instances are well suited for general-purpose workloads that require a balance of compute and memory with high-speed, low-latency local storage, including application servers, microservices, gaming servers, midsize key-value data stores, caching fleets, data logging, media processing, batch and log processing, and applications that need temporary storage such as caches and scratch files.

Here are the key specifications across the family:

M9g vCPUs Memory (GiB) Network bandwidth (Gbps) EBS bandwidth (Gbps)
medium 1 4 Up to 15 Up to 12
large 2 8 Up to 15 Up to 12
xlarge 4 16 Up to 15 Up to 12
2xlarge 8 32 Up to 17 Up to 12
4xlarge 16 64 Up to 17 Up to 12
8xlarge 32 128 17 12
12xlarge 48 192 25 18
16xlarge 64 256 34 24
24xlarge 96 384 50 36
48xlarge 192 768 100 72
metal-48xl 192 768 100 72

M9gd instances include local NVMe SSD storage. The table below shows the instance storage for each size. Compute, memory, network, and EBS bandwidth specifications are the same as M9g.

M9gd vCPUs Memory (GiB) Instance storage (GB) Network bandwidth (Gbps) EBS bandwidth (Gbps)
medium 1 4 1 x 59 NVMe SSD Up to 15 Up to 12
large 2 8 1 x 118 NVMe SSD Up to 15 Up to 12
xlarge 4 16 1 x 237 NVMe SSD Up to 15 Up to 12
2xlarge 8 32 1 x 475 NVMe SSD Up to 17 Up to 12
4xlarge 16 64 1 x 950 NVMe SSD Up to 17 Up to 12
8xlarge 32 128 1 x 1900 NVMe SSD 17 12
12xlarge 48 192 3 x 950 NVMe SSD 25 18
16xlarge 64 256 1 x 3800 NVMe SSD 34 24
24xlarge 96 384 3 x 1900 NVMe SSD 50 36
48xlarge 192 768 3 x 3800 NVMe SSD 100 72
metal-48xl 192 768 3 x 3800 NVMe SSD 100 72

Now available
M9g and M9gd instances are available in the US East (N. Virginia), US East (Ohio), US West (Oregon), and Europe (Frankfurt) Regions. M9g and M9gd instances are available for purchase through Savings Plans, On-Demand, Spot Instances, Dedicated Instances, or Dedicated Hosts. For more information, visit Amazon EC2 pricing.

To get started with M9g and M9gd instances, several resources are available. The AWS Graviton Getting Started Guide is a technical guide covering how to build, run, and optimize workloads on Graviton-based instances. The Graviton Savings Dashboard helps you track and measure the cost savings from running workloads on Graviton-based instances. AWS Transform is an AI-powered service that automates code transformations for migrating Java applications from x86 to Graviton-based Amazon EC2 instances, handling compatibility analysis, automated recompilation, dependency updates, and validation.

To learn more about Graviton-based instances, visit AWS Graviton Processors or Level up your compute with AWS Graviton.

— Esra

Editor’s Note 6/12/26: Added information about Nitro Isolation Engine

AWS Weekly Roundup: BYOM for Amazon RDS for SQL Server, AWS IoT Device SDK for Swift, and more (June 8, 2026)

8 juin 2026 à 23:27

This week, the AWS IoT Device SDK for Swift reached general availability. As a member of the Swift Server Workgroup (SSWG), this one caught my attention. The SDK brings production-ready MQTT 5 connectivity, Device Shadow, Jobs, and fleet provisioning to Swift developers on macOS, iOS, tvOS, and Linux.

Swift on IoT and Edge devices, an AI generated illustration

I’m curious to see what you will build with it. Swift on the server has matured over the past few years, and now it reaches IoT devices too. This connects to a broader trend of running Swift at the edge. WendyOS, for example, is an open-source operating system for physical AI that offers first-class Swift support for deploying apps to NVIDIA Jetson and Raspberry Pi hardware. Between server-side Swift, IoT, and edge computing, the language is showing up in places that would have surprised most people a few years ago.

Now, let’s get into this week’s AWS news.

Headlines
Amazon RDS for SQL Server supports Bring Your Own Media – Customers who migrate SQL Server applications from on-premises environments can now reuse their existing Microsoft SQL Server licenses, including Software Assurance, through Microsoft’s License Mobility program on Amazon RDS. BYOM is integrated with AWS License Manager for tracking license usage and compliance. Read more.

Amazon Cognito now supports multi-Region replication – You can now synchronize user and machine identity data, including credentials, user pool configurations, and federation setups, to a secondary user pool in a standby Region in near real-time. In the event of a disruption in the primary Region, signed-in users continue accessing their applications without re-authenticating, and registered users can sign in with their existing credentials. Multi-Region replication is available as an add-on for user pools in Essentials or Plus feature tiers across 16 Regions. Read more.

GPT-5.5, GPT-5.4, and Codex from OpenAI are now generally available on Amazon Bedrock – You can now use GPT-5.5 and GPT-5.4 in production workloads on Amazon Bedrock and build with Codex for AI-powered software development, with the same security, governance, and operational controls you already use across AWS. GPT-5.5 is the most capable model from OpenAI, excelling at agentic coding, data analysis, and multi-step autonomous tasks. Codex is available through the Codex App, the Codex CLI, and IDE integrations with Visual Studio Code, JetBrains, and Xcode. Pricing matches OpenAI first-party rates, and usage counts toward existing AWS commitments. Read more.

Last week’s launches
Here are some launches and updates from this past week that caught my attention:

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Upcoming AWS events
Learn more about AWS, browse and join upcoming AWS-led in-person and virtual events, startup events, and developer-focused events as well as AWS Summits and AWS Community Days. Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— seb

Improve your application resilience with Amazon Cognito multi-Region replication

4 juin 2026 à 00:37

As a developer advocate working with web and mobile application developers, I’ve often heard about the need to maintain consistent user authentication in the unlikely event of a regional service interruption. The increasing use of agentic AI, microservices, automation, and service accounts has sparked a similar need for machine-to-machine authentication. Today, I’m excited to share two important updates to Amazon Cognito: multi-Region replication for improved resilience, and support for customer managed keys for more control encryption control.

Many applications rely on Amazon Cognito to handle user and machine-to-machine authentication, and to manage user profiles. When building for high availability, having consistent data across different AWS Regions is a key approach, and until now, achieving that consistency came with significant challenges. Engineering teams spent significant time building and maintaining custom replication solutions to synchronize configurations across Regions. Manual export and import of user data between Regions created security risks from potential data exposure and introduced opportunities for data inconsistencies. During regional transitions, end users experienced disruptions like forced password resets and re-authentication. For machine-to-machine communications, teams had to create new app clients in the secondary region, which meant reconfiguring their applications and updating OAuth-protected resources to accept access tokens issued by the new regional issuer. These challenges made it difficult to maintain uninterrupted operations across Regions.

With multi-Region replication, Amazon Cognito automatically maintains a synchronized copy of your user data and machine secrets in a secondary AWS Region of your choice. The replication flows in one direction, from your primary Region to the secondary Region. This includes user profiles, credentials, and pool configurations. The secondary Region operates in read-only mode, focusing on maintaining authentication capabilities. Existing sessions continue uninterrupted.

When you need to direct traffic to the secondary Region, your existing users can continue signing in with their existing credentials without disruption, and currently signed-in users remain authenticated because both regions recognize access tokens issued by either region. Multi-Region replication supports all authentication methods, including federated sign-in through social providers (Amazon, Google, Apple, Facebook), Security Assertion Markup Language (SAML) and OpenID Connect (OIDC) integrations, and API authorization flows. This approach maintains availability for both customer-facing applications and machine-to-machine communications in your backend services. While authentication continues without interruption, operations like new user registration or profile updates are not available during failover.

Before configuring multi-Region replication, you must configure a multi-Region customer managed key stored in AWS Key Management Service (AWS KMS) to encrypt your user data at rest. These keys provide consistent encryption across Regions while giving you control over your encryption strategy.

How this works in practice
I start this demo with an existing Cognito user pool in the us-west-2 (Oregon) Region. I want to configure replication to us-east-1 (Northern Virginia). I also have a customer managed key replicated in these two Regions.

Configuring multi-Region replication is just three steps. The AWS Management Console guides me through the steps: set up a custom key for encryption, configure multi-region OIDC endpoints, and configure the replication itself.

First, I set up a custom AWS KMS key to encrypt the data at rest.

Cognito Multi-Region replication - initial state

I select the custom key I created. I also update the key policy to allow Amazon Cognito to access and use the key. The console shows the correct IAM policy statements to add to my key policy.

Cognito Multi-Region replication - select CMK

The console confirms when the custom key is selected and correctly configured.

Cognito Multi-Region replication - confirm CMK

Second, I follow the console instructions to configure the OIDC issuer type. On Step 2 – optional, I choose Configure.

Cognito Multi-Region replication - configure multi region OIDC 1

I make sure to update my client applications with these new endpoints. This is a required change that will need a redeployment of server-side applications and an update submission for mobile apps on the App Store and Google Play. If I don’t update the endpoints, my users will experience disruptions because requests to the old endpoints will no longer be routed correctly.

On the next screen, I select Updated. I take note of the new URLs. I confirm the changes and choose Change issuer type.

Cognito Multi-Region replication - configure multi region OIDC 2Finally, I select the target Region for replication. Only Regions where the custom encryption key is replicated are available for selection. After having chosen the target Region, I choose Create.Cognito Multi-Region replication - start the replication process.

The service prepares the replication. The time needed depends on the amount of data in the user pool.

When the replicated user pool is ready, I manually Activate it.

Cognito Multi-Region replication - replication process is complete

The replication status becomes Active. It is ready to direct traffic to the replica.

Cognito Multi-Region replication - active

Additional configurations
The console helps me to keep track of additional configurations I have to plan. When I’m using Lambda functions for custom authentication flows or SMS or email notifications, I must also deploy and configure these resources in the new Region.

Similarly, log streaming or AWS WAF configuration must be manually configured in the target Region before I start directing authentication traffic to it.

Cognito Multi-Region replication - task list

Health checks and failover
Both primary and secondary regional endpoints remain active and ready to serve your traffic at all times. To monitor system health and manage failovers, you design a strategy that aligns with your application’s specific requirements and security posture. You can implement health checks to monitor the status of authentication services in your primary Region and define criteria for when to initiate failover. These checks might look for error rates, latency patterns, or specific service alerts.

When your monitoring system detects issues meeting your failover criteria, you can redirect traffic to the secondary Region through DNS updates. This approach gives you control over the failover process while maintaining security. Consider testing your failover strategy during off-peak hours by redirecting a small portion of traffic to verify that authentication continues working as expected in the secondary Region.

When using managed login and federation with custom domains, you can also use the built-in traffic routing feature by providing an Amazon Route 53 health check ID.

Pricing and availability
Multi-Region replication is available today as an add-on feature for Amazon Cognito customers using Essentials and Plus tier. For user authentication, the add-on costs $0.0045 per monthly active user per replica Region for Essentials tier customers and $0.006 per monthly active user per replica region for Plus tier customers. For machine-to-machine (M2M) authentication, the add-on is a 30% charge on top of the standard volume-based pricing for successful tokens issued. For detailed pricing information, see Amazon Cognito pricing.

Multi-Region replication is available in the following Regions: US East (Ohio, N. Virginia), US West (N. California, Oregon), Asia Pacific (Mumbai, Seoul, Singapore, Sydney, Tokyo), Canada (Central), Europe (Frankfurt, Ireland, London, Paris, Stockholm), and South America (São Paulo).

Any of these Regions can be used as the source or the destination for the replication.

Support for customer managed keys is available for the Essentials and Plus tiers. It is available in the following Regions: US East (Ohio, N. Virginia), US West (N. California, Oregon), Africa (Cape Town), Asia Pacific (Hong Kong, Hyderabad, Jakarta, Malaysia, Melbourne, Mumbai, New Zealand, Osaka, Seoul, Singapore, Sydney, Thailand, Tokyo), Canada (Central), Canada West (Calgary), Europe (Frankfurt, Ireland, London, Milan, Paris, Spain, Stockholm, Zurich), Israel (Tel Aviv), Mexico (Central), South America (São Paulo), and AWS GovCloud (US-East, US-West)

From my conversations with customers, maintaining business continuity during regional incidents while meeting security requirements is a high priority. Multi-Region replication provides the capability to build more resilient applications without managing complex replication logic yourself. The automatic synchronization of user data and configurations reduces operational overhead while maintaining security.

For customers in regulated industries, the new support for customer managed keys provides additional control over data encryption. You can now use your own encryption keys to protect user data at rest, helping you meet regulatory requirements in industries like healthcare and financial services.

To get started with multi-Region replication and customer managed key encryption, visit the Amazon Cognito console or see the documentation for detailed setup instructions. I look forward to hearing how you use this feature to strengthen your application architecture.

— seb
❌